Artificial intelligence is transforming how organizations process information, automate workflows, and deliver personalized experiences. From conversational AI and healthcare applications to financial services and enterprise automation, modern AI systems depend on large volumes of text data to learn language patterns and generate meaningful insights. However, this data frequently contains personally identifiable information (PII), creating a critical challenge for organizations seeking to develop powerful AI models without compromising individual privacy. Names, email addresses, phone numbers, financial records, and medical identifiers can expose sensitive information when incorporated into training datasets without appropriate safeguards.
As privacy expectations rise, businesses must rethink how they prepare, annotate, and manage textual data. PII detection and text de-identification annotation provide a practical foundation for privacy-aware AI training. These processes help identify sensitive information, apply standardized labels, and replace personal identifiers while preserving the contextual information required for machine learning. As an AI data services provider, Annotera helps organizations prepare structured, high-quality text datasets that support reliable AI development. By emphasizing annotation consistency and quality-focused workflows, Annotera enables AI teams to address data preparation challenges while keeping privacy considerations central to their strategies.
Key Points
- Protect Sensitive Information: PII detection identifies personal identifiers, including names, email addresses, phone numbers, and financial details, helping reduce privacy risks in AI training datasets.
- Preserve Data Utility Through De-Identification: Replacing sensitive information with standardized placeholders helps retain valuable contextual information while supporting privacy-aware AI model development.
- Ensure Annotation Accuracy and Quality: Clear annotation guidelines, human review, and multi-stage quality checks help minimize missed identifiers, inconsistent labeling, and potential re-identification risks.
- Scale Privacy-Safe AI Training with Annotera: Annotera supports structured text annotation workflows that help AI teams prepare high-quality datasets while integrating privacy considerations into data preparation strategies.
What Is PII Detection and Text De-Identification Annotation?
PII detection annotation involves identifying and labeling text that directly or indirectly identifies an individual. Common examples include personal names, telephone numbers, email addresses, residential addresses, identification numbers, and sensitive financial information. Text de-identification annotation builds on this process by identifying which portions of a document should be masked, replaced, removed, or transformed before the data is used for AI training or evaluation. Consider a customer support message: Original text: “My name is Sarah Mitchell. Please contact me at [sarah.mitchell@example.com] regarding my account.” De-identified text: “My name is [PERSON]. Please contact me at [EMAIL_ADDRESS] regarding my account.” In this example, sensitive entities are replaced with standardized placeholders while the sentence retains its essential meaning. The distinction is important: detection identifies sensitive information, annotation assigns labels to it, and de-identification transforms the text according to predefined rules. De-identification does not automatically guarantee anonymity. Contextual details and combinations of seemingly harmless information may still reveal an individual’s identity. Organizations must therefore assess residual privacy risks before approving datasets for use.
Why PII Annotation Is Essential for Responsible AI Training
1. Protecting Personal Information
Training datasets often contain sensitive details embedded within otherwise valuable text. Without appropriate identification and handling, this information can be unnecessarily exposed during data processing, sharing, or model development. PII annotation helps organizations identify these details before training and establish consistent rules for handling them. Human-reviewed annotation is particularly valuable when personal information appears in informal conversations, ambiguous statements, or unexpected formats.
2. Supporting Privacy and Regulatory Requirements
Organizations operating across markets must consider applicable privacy regulations, including the General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA), as amended by the California Privacy Rights Act (CPRA). PII detection and de-identification can support privacy management by helping organizations identify sensitive information and implement appropriate data-handling procedures. However, annotation alone does not establish regulatory compliance. Lawful processing, security controls, retention policies, and other applicable obligations must also be addressed.
3. Preserving Training Data Utility
Removing every document containing personal information can significantly reduce the amount of usable training data. De-identification offers a more targeted approach by replacing sensitive entities while retaining relevant language patterns and contextual relationships. For example, a conversational AI model can learn how to resolve a billing complaint without requiring access to a customer’s actual name, telephone number, or account identifier. This balance between privacy and data utility is essential for building effective AI systems.
“Privacy-safe AI training begins with understanding what information a model needs—and what information it does not.”
This principle highlights the importance of purpose-driven data preparation: retain the information necessary for learning while reducing unnecessary exposure of personal identifiers.
Key Steps in PII Detection and Text De-Identification Annotation
A reliable annotation workflow combines clearly defined labeling rules, trained annotators, quality assurance, and appropriate technical safeguards.
Step 1: Define PII Categories and Annotation Guidelines
The first step is to identify the sensitive entity categories relevant to the project. These may include personal identifiers, contact information, financial details, healthcare identifiers, and confidential organizational references. Annotators require explicit instructions for distinguishing between entity types, handling overlapping labels, and identifying ambiguous references. Consistent guidelines reduce interpretation differences and improve annotation reliability.
Step 2: Identify and Label Sensitive Entities
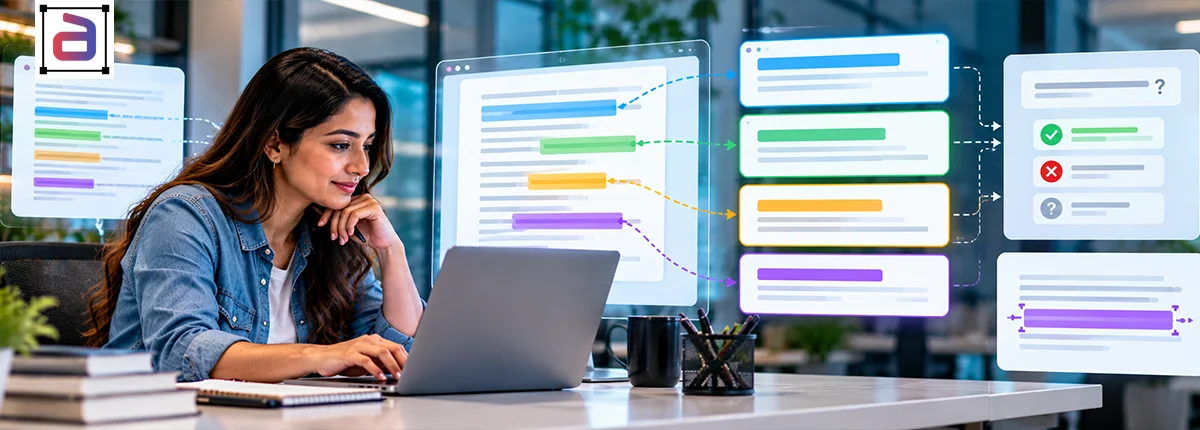
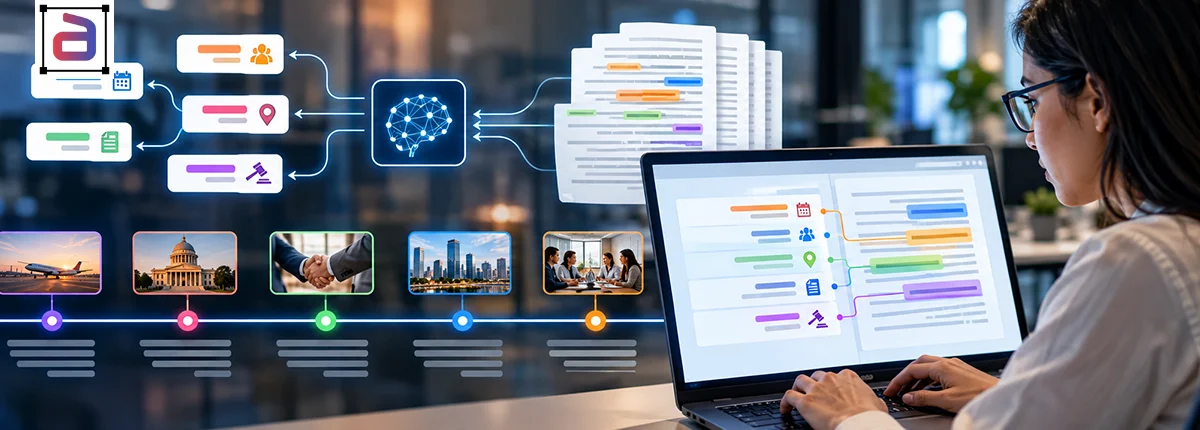
Annotators examine the text and mark relevant spans using standardized labels. The process should account for spelling variations, abbreviations, multilingual expressions, and context-dependent identifiers. For example, a telephone number written with spaces or international dialing codes should still be recognized as a potential sensitive entity. Similarly, names embedded in conversational language may require contextual interpretation rather than simple pattern matching.
Step 3: Apply Appropriate De-Identification Rules
After identifying sensitive information, the dataset can be transformed according to predefined requirements. Common approaches include masking, replacement with standardized placeholders, removal of unnecessary identifiers, and consistent pseudonymization where preserving relationships is important. The appropriate method depends on the intended AI application. Pseudonymized information may remain linkable to an individual and must therefore receive suitable protection.
Step 4: Conduct Quality Assurance
Even small annotation errors can leave sensitive information exposed or unnecessarily remove useful context. Quality assurance should evaluate both entity detection and the accuracy of the transformed dataset. Useful checks include expert review, inter-annotator agreement, automated pattern validation, and targeted sampling of difficult examples.
Step 5: Validate Privacy and Dataset Quality
Before a dataset enters the training pipeline, teams should check for missed identifiers, inconsistent replacements, and contextual clues that could enable re-identification. The final review should also confirm that de-identification has preserved the information needed for the intended machine learning task. Privacy protection and dataset utility must be assessed together.
Common Challenges in PII Detection and De-Identification
Despite advances in automated detection, identifying sensitive information remains challenging.
- Context-dependent PII: A person’s identity may be inferred from a combination of job title, location, organization, and other details.
- Unstructured and multilingual text: Informal writing, spelling errors, abbreviations, and regional language variations can complicate entity identification.
- False positives and false negatives: Incorrect labels can remove valuable information, while missed identifiers can create privacy risks.
- Scalability and consistency: Large datasets require repeatable annotation standards and quality controls across different annotators and data batches.
Addressing these challenges requires a combination of carefully designed guidelines, human expertise, suitable automation, and ongoing quality evaluation.
How Text Annotation Outsourcing Services Support Privacy-Safe AI
Building an internal PII annotation operation requires trained personnel, annotation infrastructure, quality management, and ongoing workflow oversight. These requirements can become particularly demanding when organizations process large, multilingual, or industry-specific datasets. Professional text annotation outsourcing services can help AI teams manage annotation at scale while establishing consistent labeling practices and structured quality checks. An experienced text annotation company can support organizations through task-specific annotation guidelines, sensitive entity labeling, multi-stage quality reviews, and structured dataset preparation. However, outsourcing sensitive data processing requires careful partner selection. Organizations should evaluate confidentiality procedures, access restrictions, workforce training, security safeguards, contractual responsibilities, and applicable data-processing requirements. A well-governed outsourcing arrangement can extend annotation capacity without replacing the organization’s responsibility for protecting personal information.
How Annotera Helps Build Privacy-Aware AI Datasets
At Annotera, we understand that trustworthy AI begins with carefully prepared data. Our text annotation capabilities support natural language processing, conversational AI, enterprise automation, and other language-driven applications that depend on structured, high-quality datasets. Annotera helps organizations establish consistent annotation workflows through:
- Structured entity labeling: Standardized annotation guidelines support consistent identification of relevant text entities.
- Quality-focused review: Review workflows help identify inconsistencies and improve annotation reliability.
- Scalable data preparation: Flexible processes support projects with varying volumes, complexity, and domain requirements.
- Task-specific annotation: Annotation requirements can be aligned with the intended application, dataset characteristics, and project objectives.
For projects involving sensitive information, PII detection and de-identification requirements should be integrated into a broader data governance framework with appropriate security controls and clearly defined responsibilities. By combining structured annotation practices with a focus on dataset quality, Annotera helps AI teams establish a stronger foundation for responsible model development.
Conclusion: Make Privacy a Priority in AI Data Preparation
PII detection and text de-identification annotation are essential considerations for organizations building AI systems with real-world text data. Identifying sensitive entities, applying appropriate transformation rules, and validating the resulting datasets can help reduce privacy risks while preserving valuable training context. However, effective privacy-aware data preparation requires more than automated detection or basic redaction. Clear annotation guidelines, trained reviewers, rigorous quality assurance, and appropriate data governance must work together. For organizations seeking dependable text annotation outsourcing services, the right partner can help establish scalable workflows that align data quality objectives with privacy considerations. Annotera helps businesses turn unstructured text into structured, high-quality data for AI development. Ready to strengthen your AI data preparation strategy? Connect with Annotera to discuss your text annotation requirements and explore how tailored annotation workflows can support your next AI initiative. Build better datasets, strengthen quality controls, and move toward more responsible AI development with Annotera.
A closely related read: PII Redaction and Anonymization in Text Datasets: Balancing Privacy and Model Utility.