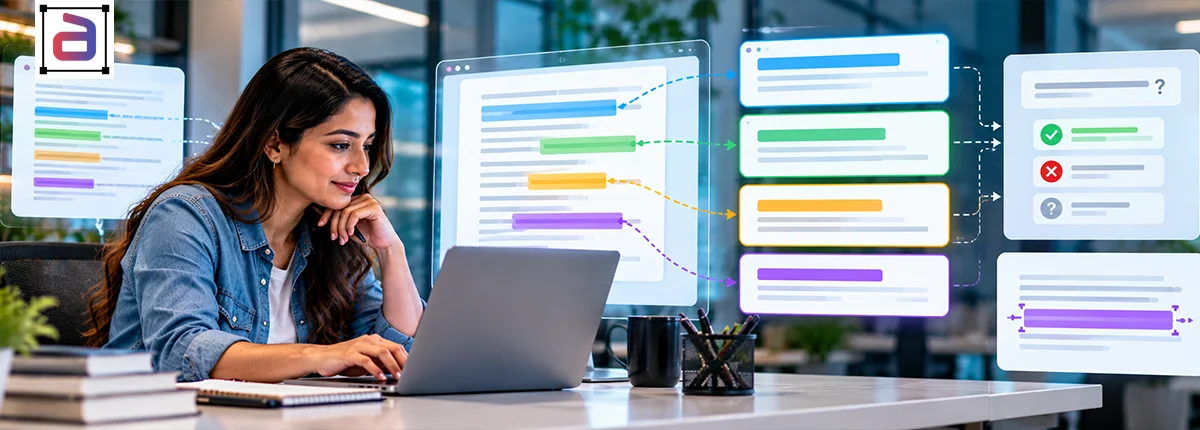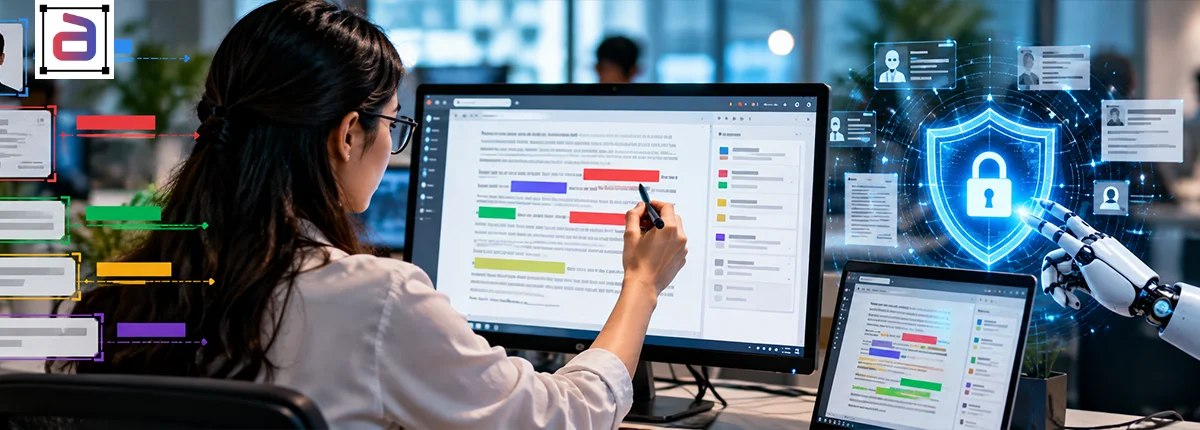
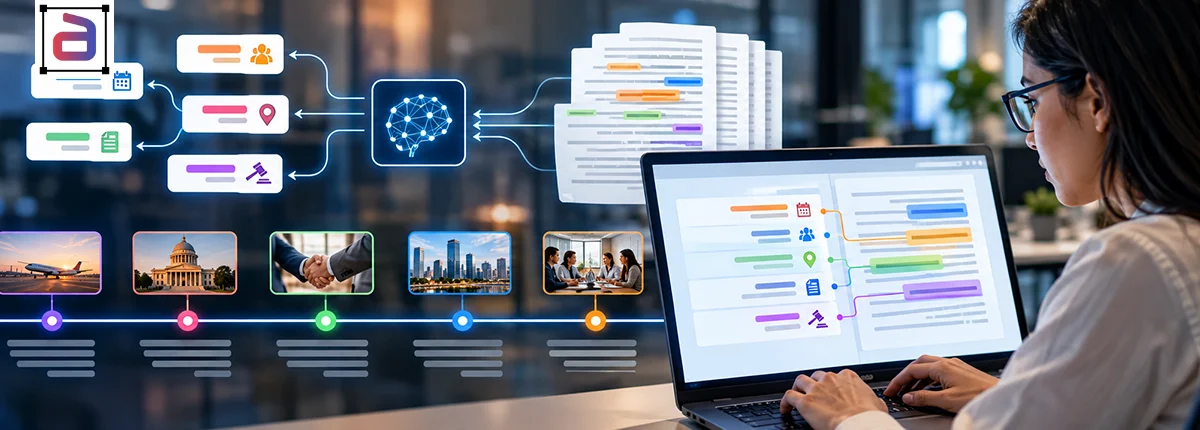
Every document tells a story. A financial report describes market developments, a medical record captures a patient’s treatment journey, and a news article documents events that shape the world. Yet, for artificial intelligence (AI) systems, understanding these stories requires more than reading words. Models must identify what happened, determine when it happened, and establish how different events connect over time. This is where event extraction and temporal annotation become essential to Natural Language Processing (NLP). These techniques transform unstructured text into structured, time-aware information, enabling AI models to reconstruct event sequences, interpret historical context, and uncover relationships that might otherwise remain hidden.
Consider a simple statement: “The company announced a new product in March after completing its research and development phase in January.” An effective NLP system must identify both events, recognize their respective time references, and establish the chronological relationship between them. Achieving this level of understanding requires high-quality training data. Through structured annotation workflows and specialized text annotation outsourcing services, organizations can prepare datasets that help NLP models interpret complex documents with greater consistency. At Annotera, we recognize that accurate AI begins with accurately labeled data. Event extraction and temporal annotation represent important steps toward building intelligent systems that understand not just what a document says, but how its information unfolds over time.
Key Points
- Extract Meaningful Events: Identify event triggers, participants, and contextual details to transform unstructured text into structured information for NLP models.
- Establish Temporal Relationships: Recognize dates, time expressions, and event sequences to build accurate timelines and understand how events connect.
- Improve Annotation Quality: Apply standardized annotation guidelines, contextual analysis, and quality assurance to address ambiguity and maintain dataset consistency.
- Strengthen NLP Performance with Annotera: Leverage Annotera’s text annotation outsourcing services to develop high-quality training datasets for information extraction, document intelligence, and automated timeline generation.
What Is Event Extraction and Temporal Annotation?
Event extraction is an NLP task that identifies significant events in textual content and captures their associated details. These details may include the event trigger, participants, affected entities, location, and other contextual information. For example, in the sentence “The board approved the acquisition on September 12,” an annotation framework can identify approved as the event trigger, the board as the agent, the acquisition as the affected entity, and September 12 as the temporal expression. Temporal annotation adds another layer of understanding by identifying time expressions and labeling relationships between events. It helps AI systems determine whether an event occurred before, after, during, or simultaneously with another event. Together, these techniques enable machines to convert scattered textual references into structured timelines. As a guiding principle for NLP development, consider this statement:
“An event without context is a data point; an event connected to time becomes part of a story.”
This original statement captures the value of temporal annotation: chronological context makes extracted information more meaningful and useful for downstream AI applications.
Why Building Timelines from Unstructured Text Matters
Organizations possess vast amounts of information in emails, reports, customer conversations, legal documents, clinical notes, and news archives. Much of this information remains difficult to analyze because it is stored as free-flowing text rather than structured data. Event extraction and temporal annotation help bridge this gap by enabling AI systems to reconstruct sequences of events and understand how situations evolve.
- Healthcare and clinical intelligence: Medical records often contain references to symptoms, diagnoses, medications, and follow-up visits across different dates. Temporal annotation helps organize these details into patient timelines, supporting applications that analyze clinical histories.
- Legal document analysis: Legal investigations frequently involve contracts, witness statements, correspondence, and incident reports. Structured event timelines can help identify the sequence of reported events and support document review.
- Financial intelligence: Financial reports contain corporate announcements, acquisitions, regulatory developments, and market events. Temporal relationships help analytical systems organize these developments chronologically.
- News monitoring and research: News articles may revisit earlier events while introducing new developments. Event extraction helps systems connect related information across reports and track how a story changes over time.
- Customer experience analytics: Support conversations can reveal when an issue began, what troubleshooting steps were attempted, and when a resolution occurred. Temporal annotation helps transform these interactions into structured service histories.
Across these applications, reliable timelines depend on the quality and consistency of the underlying annotated datasets.
Key Components of Event Extraction and Temporal Annotation
Building dependable event timelines requires a comprehensive annotation framework that captures individual events and their relationships.
1. Event Identification and Trigger Labeling
The first step is identifying meaningful events within a document. Event triggers are the words or phrases that express an occurrence, action, or change. For example, in the sentence “The research team published its findings after completing the clinical trial,” the annotation process identifies two events: completing the trial and publishing the findings. Annotators must distinguish actual events from hypothetical scenarios, general descriptions, and statements that do not represent relevant occurrences. Clear event definitions help prevent inconsistent labels and improve model performance.
2. Event Argument Annotation
Identifying an event is only the beginning. AI models also need to understand who participated in the event, what was affected, and where the event occurred. Consider the sentence: “The manufacturer recalled 5,000 vehicles following the discovery of a braking defect.” A structured annotation framework can identify the recall and defect discovery as separate events, along with their associated entities and contextual details. This information helps NLP models extract meaningful event representations rather than isolated keywords.
3. Temporal Expression Recognition and Normalization
Temporal expressions can be explicit, such as March 15, 2026, or relative, such as three weeks earlier, the following morning, and last quarter. Annotators must identify these expressions and, where sufficient context is available, normalize them into standardized temporal values. For instance, the phrase “The company announced the acquisition two days later” requires a reference event to determine the actual date. If that reference is missing, the annotation should preserve the uncertainty rather than invent a date. Accurate temporal labeling allows models to interpret dates consistently across documents and applications.
4. Temporal Relation Annotation
A timeline becomes meaningful when individual events are connected through temporal relationships. Common relationships include:
- Before and after: Establishing the chronological order of two events.
- During: Identifying an event that occurs within the duration of another.
- Simultaneous: Representing events that occur at the same time.
- Overlap: Capturing events whose time intervals partially intersect.
For example, “The team started development in January, conducted testing in March, and released the product in April” establishes a clear sequence of development, testing, and release. Annotating these relationships enables AI systems to reconstruct event sequences even when information appears across multiple sentences or documents.
Common Challenges in Temporal Annotation
Despite its potential, temporal annotation involves challenges that can compromise dataset reliability if they are not addressed systematically.
- Ambiguous time references: Expressions such as recently and earlier that year depend on contextual information that may not always be available.
- Complex event structures: A single sentence may describe several events, participants, and temporal relationships, requiring careful annotation to avoid missing connections.
- Implicit chronology: Writers frequently imply event order without explicitly providing dates or time markers. Interpreting these relationships requires contextual reasoning.
- Conflicting information: Different documents may report different dates for the same event. Annotation guidelines must distinguish conflicting source information from verified chronology.
- Inconsistent labeling: Without standardized rules, annotators may disagree about event boundaries, temporal intervals, or relationship categories.
Addressing these challenges requires detailed annotation guidelines, trained annotators, contextual review, and robust quality assurance processes.
How Annotera Helps Strengthen NLP Training Data
Reliable event extraction begins with well-structured training datasets. However, creating these datasets at scale can be challenging, particularly when projects involve large document collections, specialized terminology, and complex temporal relationships. An experienced text annotation company can help AI teams establish consistent labeling frameworks, improve annotation quality, and prepare datasets aligned with specific model requirements. At Annotera, our data annotation expertise supports organizations developing NLP and document intelligence applications. Structured annotation workflows can support tasks such as event identification, event argument labeling, temporal expression recognition, and relationship annotation. Our approach emphasizes several important principles:
- Clear annotation standards: Consistent guidelines help ensure that events and temporal relationships are labeled according to predefined rules.
- Context-aware labeling: Reviewing relevant document context helps annotators interpret ambiguous expressions and distinguish related events.
- Quality assurance: Review procedures help identify missing labels, incorrect relationships, and inconsistencies across datasets.
- Scalable workflows: Structured processes help organizations manage growing annotation requirements as their AI initiatives expand.
Depending on project requirements, human annotation can also be combined with automated pre-annotation to accelerate repetitive tasks while retaining human oversight for ambiguous and complex cases. The objective is to provide AI teams with reliable, application-ready training data that supports more effective information extraction and timeline reconstruction.
Best Practices for Building Reliable Event Timelines
Organizations can improve dataset quality by following a disciplined annotation strategy.
- Define an event taxonomy: Establish clear categories for relevant events and specify how event triggers, participants, and contextual attributes should be labeled.
- Standardize temporal rules: Document how to handle explicit dates, relative expressions, uncertain references, and overlapping time intervals.
- Preserve document context: Annotators should consider surrounding sentences and relevant source information when determining temporal relationships.
- Implement multi-stage quality checks: Review event identification, argument labeling, temporal normalization, and relationship consistency to detect errors before model training.
- Measure annotation quality continuously : Use predefined quality metrics and targeted reviews to identify recurring disagreements and refine annotation guidelines.
These practices help produce datasets that are consistent, traceable, and suitable for sophisticated NLP applications.
Conclusion: Turn Unstructured Text into Structured Intelligence with Annotera
Unstructured text contains valuable information about events, decisions, relationships, and developments. However, unlocking this information requires AI systems to understand not only individual events but also their temporal context. Event extraction and temporal annotation provide the foundation for transforming scattered textual references into coherent timelines. By identifying event triggers, capturing relevant arguments, recognizing temporal expressions, and labeling relationships, organizations can develop NLP systems that interpret complex documents more effectively. The quality of these capabilities ultimately depends on the quality of the training data.
Consistent annotation standards, contextual understanding, and rigorous quality assurance are essential for creating datasets that support reliable AI performance. Annotera helps organizations build stronger AI data pipelines through structured text annotation solutions designed to support accuracy, consistency, and scalability. Whether you are developing document intelligence platforms, automated reporting systems, legal analytics tools, or advanced information extraction models, investing in high-quality annotation can help unlock greater value from unstructured text.
Ready to Build Smarter NLP Solutions?
Give your AI models the structured data they need to understand events, interpret timelines, and extract meaningful insights from complex documents. Partner with Annotera for text annotation outsourcing services tailored to your AI training requirements. Contact our team today to discuss your project and discover how high-quality annotation can strengthen your NLP development workflow.
A closely related read: Event Extraction and Temporal Annotation: Building Timelines from Unstructured Text.