Video Data That Trains Smarter Motion Tracking AI Models

High-quality continuous video footage collected across every domain your model will operate in — structured, labeled by scene, and ready for annotation from day one.

Video Data Collection Services for Object Tracking, Action Recognition, and Event Detection AI

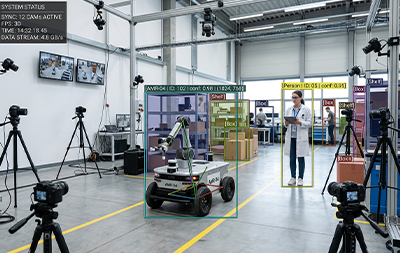
Video data collection sources continuous footage that AI models need to understand motion, detect objects over time, recognize human actions, and identify events as they unfold. Annotera collects video across dashcam and roadway environments, sports and broadcast feeds, manufacturing floors, behavioral and consumer settings, surveillance installations, and more — capturing the temporal and spatial context that still images alone cannot provide.

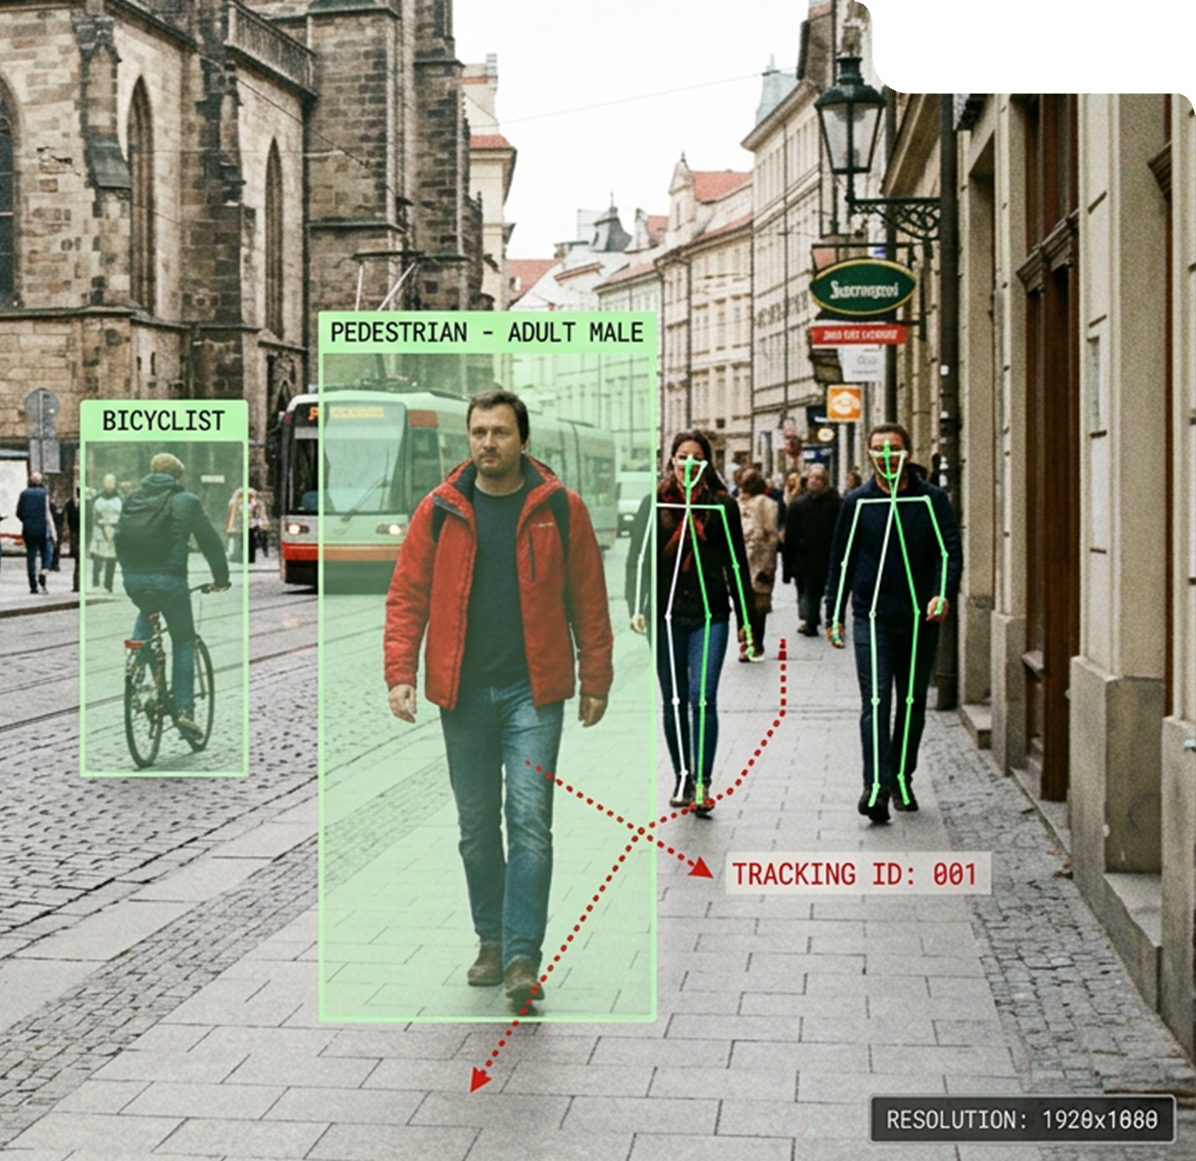
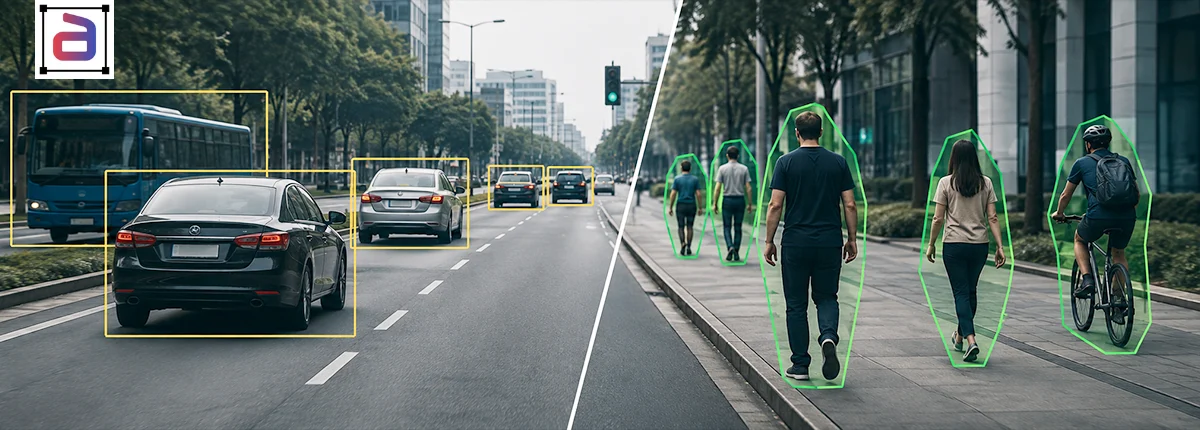
Every video collection engagement is scoped against your annotation taxonomy before a single frame is captured, so footage arrives segmented by scene type, event class, and camera angle — structured for object tracking, action segmentation, event detection, and multi-object labeling. With 20+ years of BPO experience and a 350+-person delivery team, Annotera provides compliant, scalable, annotation-ready video datasets for autonomous vehicles, sports analytics, industrial AI, retail, security, healthcare, and beyond.

Services We ProvideComprehensive Video Data Collection Services Across Every Domain and Use Case

Annotera’s video data collection services cover the full range of continuous footage categories that AI and ML teams need — each scoped to the temporal structure, scene diversity, and annotation task it will feed.
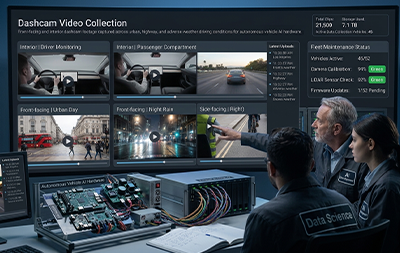
Dashcam Video Collection

Front-facing and interior dashcam footage captured across urban, highway, and adverse weather driving conditions for autonomous vehicle AI hardware.

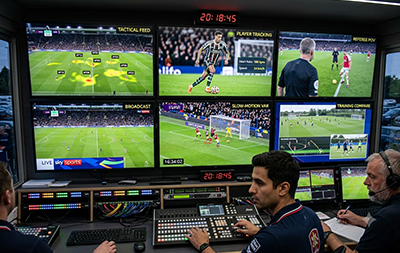
Sports Broadcast Video

Multi-angle match footage, training ground recordings, and broadcast feeds from live sporting events for player tracking and referee assist training.

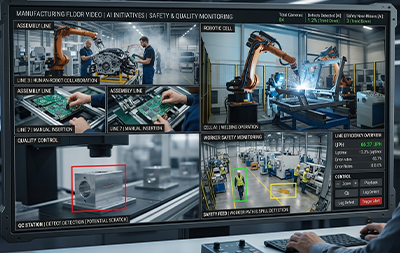
Manufacturing Floor Video

Continuous footage from assembly lines, robotic cells, and quality control stations for defect detection and worker safety monitoring AI initiatives.

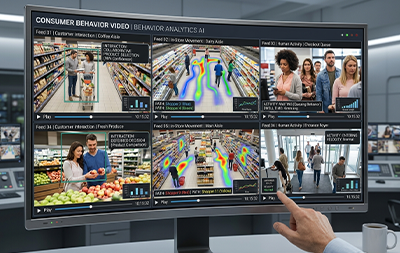
Consumer Behavior Video

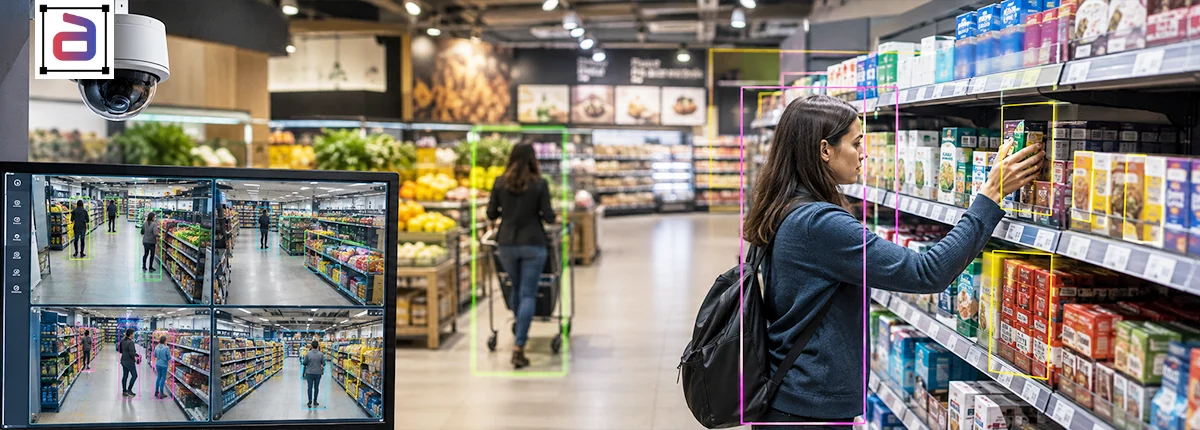
Customer interaction, in store movement, and human activity footage from retail and public environments for behavior analytics AI model applications.

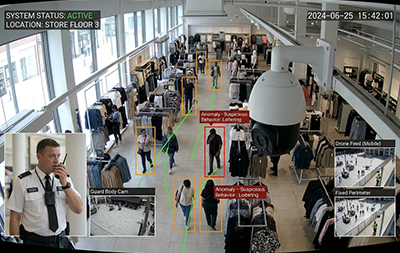
Security Surveillance
Video

Fixed, PTZ, and mobile camera footage across perimeter, indoor, and public space environments for intrusion detection and anomaly recognition system.

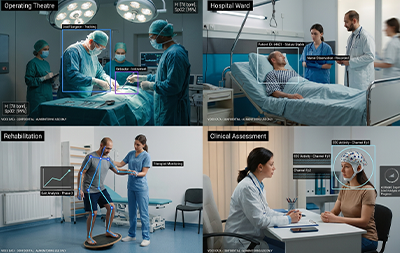
Medical Clinical
Video

Operating theatre, ward, rehabilitation, and clinical assessment footage under HIPAA aware handling for surgical AI and patient monitoring programs.

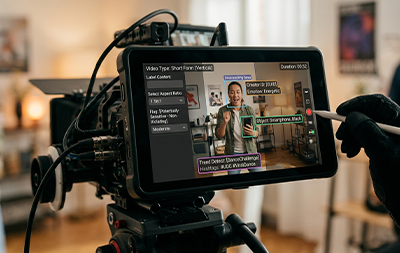
User-Generated Video Collection

Short form and long form consumer videos from licensed sources and staged capture for content moderation, trend detection, and creator infrastructure.

Multi-Camera Video Collection

Omnidirectional and synchronized multi camera footage from immersive, robotics, and simulation environments for spatial AI training model programs.

Security & ComplianceEnterprise-Grade Data Security and Regulatory Compliance

Video footage frequently captures identifiable individuals, sensitive environments, and proprietary processes. Every Annotera video collection engagement includes consent management, de-identification protocols, and the regulatory compliance framework your program requires.

Industries Video Data Built to Outperform for Every Vertical You Serve

Continuous videos are the modality of motion, context, and time. Annotera delivers video datasets tailored to the temporal requirements, compliance framework, and annotation taxonomy of each industry — from single-location pilots to continuous multi-site collection programs.

OUR PROCESSFrom Footage Brief to Annotation-Ready Video Dataset

Every Annotera video data collection engagement follows a structured four-stage workflow — ensuring footage arrives at the annotation team pre-segmented by scene, event class, and camera angle, and scoped to the temporal labeling taxonomy.
Scope & Define

We define video categories, camera setups, scene types, temporal requirements, subject consent, and the annotation taxonomy — from bounding box to action segmentation — before capture begins.

Collect & Capture

Our specialists source footage via direct camera deployment, licensed video partners, or staged scenario recording — matched to the resolution, frame rate, and environment your model needs.

Validate & QA

Every clip is reviewed for scene coverage, resolution, motion quality, temporal consistency, and compliance before handoff — quality issues caught here, not at the labeling stage.

Delivery & Scale

Footage delivered segmented by scene, event class, and camera angle on schedule — with the option to scale to additional environments, angles, or footage categories as your model grows.

FeaturesVideo Data Collection Capabilities Built for Tracking and Action Recognition AI

Video collection requires control over temporal structure, scene diversity, frame rate, resolution, and annotation readiness in ways that image collection does not. Annotera’s features are built around these demands.

Temporal & Scene Diversity

Footage captured across a range of times of day, environments, activity types, and event conditions, ensuring your model generalizes well to all real production requirements today.

De-Identification & Privacy Compliance

Facial blur, license plate redaction, and environment anonymization applied during QA for every piece of footage capturing identifiable individuals in public or regulated spaces.

Collection-to-Annotation Pipeline

Video footage routes directly into Annotera's annotation team for bounding boxes, tracking, action segmentation, and event labeling with zero added handoff gaps or further delay ever.

Why Choose UsSix Reasons AI Teams Choose Annotera for Video Data Collection

We deliver secure, scalable, and cost-effective video data collection services. AI and computer vision teams trust us to source the continuous footage their models need — at the right temporal structure, resolution, and compliance standard.

Industry Expertise

20+ years of BPO delivery experience applied to dashcam, sports, surveillance, and industrial video collection, backed by a proven global operation and strict protocols worldwide.

Affordable Pricing

Cost effective video sourcing that maintains high quality, so teams can build robust action recognition and tracking pipelines without overextending strict budgets on production.

Secure Workflows

ISO 27001 aligned and SOC compliant processes protect video footage at every stage, with strict access controls, encrypted transfer, and secure storage built in properly and safely.

Consistent Quality

Every video dataset is reviewed for scene coverage, motion quality, temporal consistency, and annotation readiness before handoff, guaranteeing structured usable output always.

Scalable Workforce

350+ trained specialists and a global delivery network support video collection at any volume, from a small pilot clip to a continuous multi-site production program worldwide always.
Connect with an Expert

    Your information will be securely sent to and stored in Google Sheets for the purpose of processing your form submission.

    Frequently Asked QuestionsGot Questions? We’ve Got Answers for You

    Here are answers to common questions about video data collection, footage types, compliance, and how continuous video datasets fit into AI and ML training pipelines.

    AI video data collection is the process of sourcing and capturing continuous footage — dashcam, sports, manufacturing, surveillance, behavioral, or clinical video — that machine learning models are trained on. Unlike still images, video provides temporal context: motion, action sequences, and events unfolding over time. Models for object tracking, action recognition, and event detection cannot train effectively without it.

    Image data collection sources still frames; video collection sources continuous temporal sequences. Video provides motion context, inter-frame consistency, and event timing that static images cannot capture. Many AI programs use both — images for spatial recognition and video for temporal understanding — and Annotera provides both services under the same pipeline.

    Annotera collects dashcam and in-vehicle footage, sports and broadcast video, manufacturing and shop floor recordings, consumer and behavioral footage, security and surveillance video, medical and clinical recordings, social and user-generated content, and 360° and multi-camera footage. Each type is captured at the resolution, frame rate, and scene diversity the annotation task requires.

    Yes. Many engagements include synchronized multi-angle or multi-camera capture, delivering footage from overlapping viewpoints at the same timestamp. This is particularly useful for sports AI, autonomous vehicle programs, and robotics training that need cross-view consistency.

    Consent protocols are built into the collection design before any recording begins. For footage capturing identifiable individuals in public or private spaces, we apply facial blur, license plate redaction, and environment anonymization during QA. GDPR-compliant handling is standard for EU data subjects, and HIPAA-aware protocols apply to all healthcare and clinical videos.

    Yes. Footage is segmented by scene type and event class, then routed directly into Annotera’s annotation team for bounding box, tracking, action segmentation, and event labeling. There is no handoff gap between collection and labeling — one partner handles both.

    Frame rate and resolution are defined in the collection brief before capture begins and matched to the annotation platform and model architecture requirements. Common deliveries include 1080p at 30fps for behavioral and surveillance video, 4K at 60fps for sports analytics, and variable-rate dashcam footage that matches real deployment sensor specs.

    Our BlogsTransformative AI
    Solutions in action

    Get A Quote