Frame-Accurate Video Annotation for Computer Vision

Object tracking, event tagging, keypoints and 3D cuboids labeled consistently across every frame by dedicated teams working to your guidelines. Start with a free 48-hour pilot on your own clips.

Video Annotation Services for Computer Vision and Robotics

Video Annotation Services Built for Temporal Accuracy

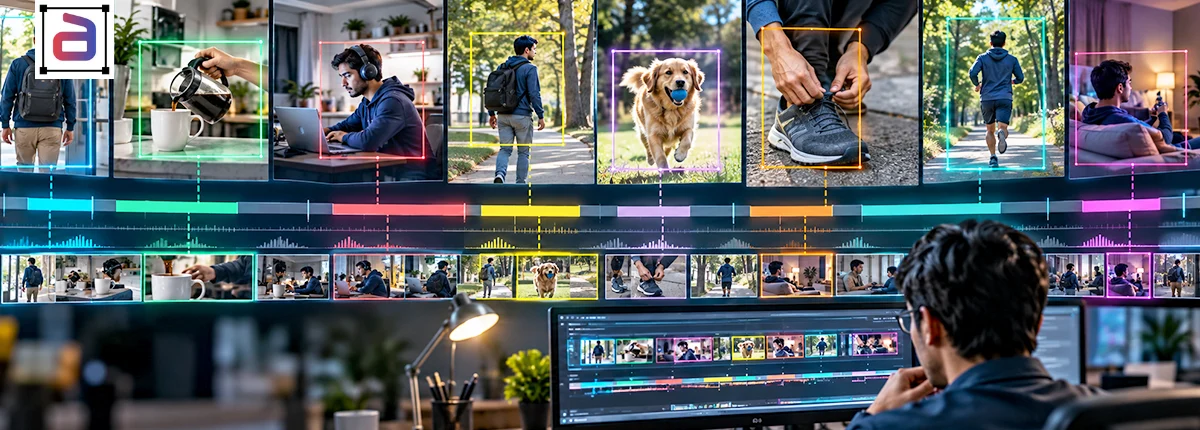
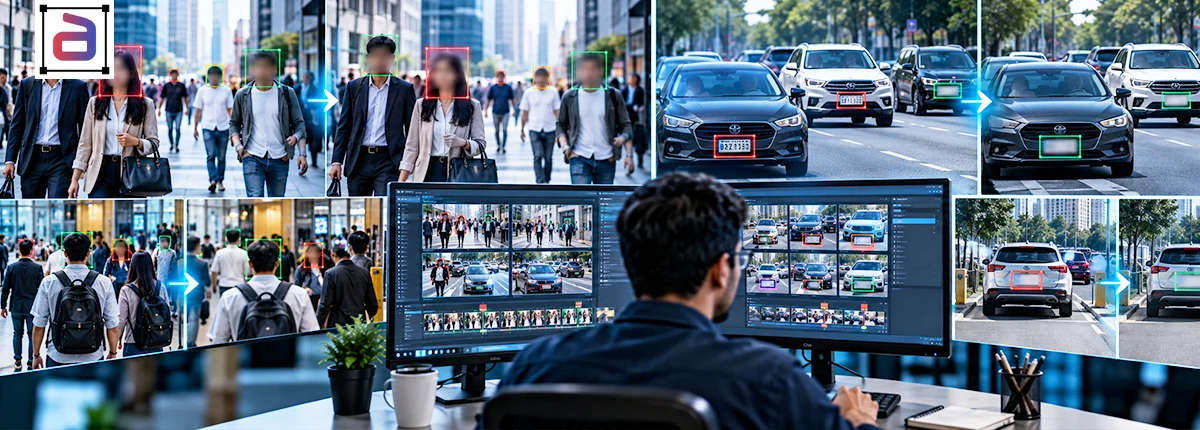
Video models learn from sequences, not single images. Annotera’s video annotation services label objects, people and events across every frame so that identities stay consistent, actions have precise start and end points, and partly hidden objects are handled the same way every time. Dedicated annotators work to your guidelines, and every batch is checked against a gold set before it ships.

Video Labeling Services for Every Technique

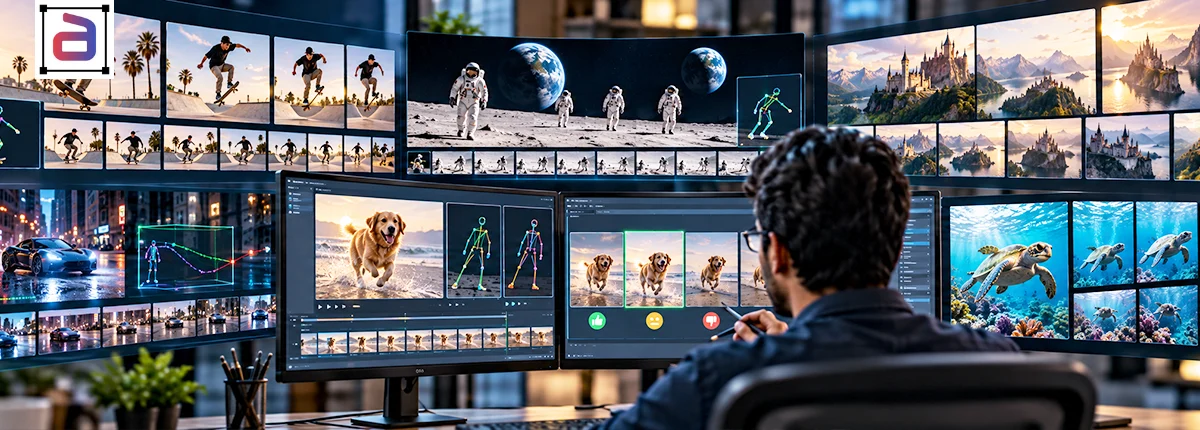
Our video labeling services cover bounding boxes and 3D cuboids tracked across frames, polygons and keypoints, polylines for lanes, multi-object tracking with persistent IDs, event and activity tagging, occlusion and visibility states, audio-video sync and frame-level validation. Programs combine frame-by-frame labeling with interpolation between keyframes, so effort goes where fast motion and occlusion make it necessary. Our article on frame-by-frame vs interpolated video annotation explains the trade-off.

From Pilot Clips to Production Volume

Video annotation supports autonomous vehicle, robotics, retail, security, public safety and healthcare teams, from a first set of pilot clips to thousands of hours of footage. If you are new to the topic, our guide to what data annotation is covers the basics, and our image annotation services handle still images on the same QA framework.

ServicesVideo Annotation Services by Technique

Choose the technique your model needs, or combine several in one program. Each page covers use cases, edge-case rules and how quality is measured for that method.

Boxes drawn and tracked across frames for fast, reliable object detection in moving footage.

Cuboids that keep depth, size and heading consistent as objects move through the scene.

Polygon Annotation

Precise outlines for irregular shapes, carried across frames as their boundaries change.

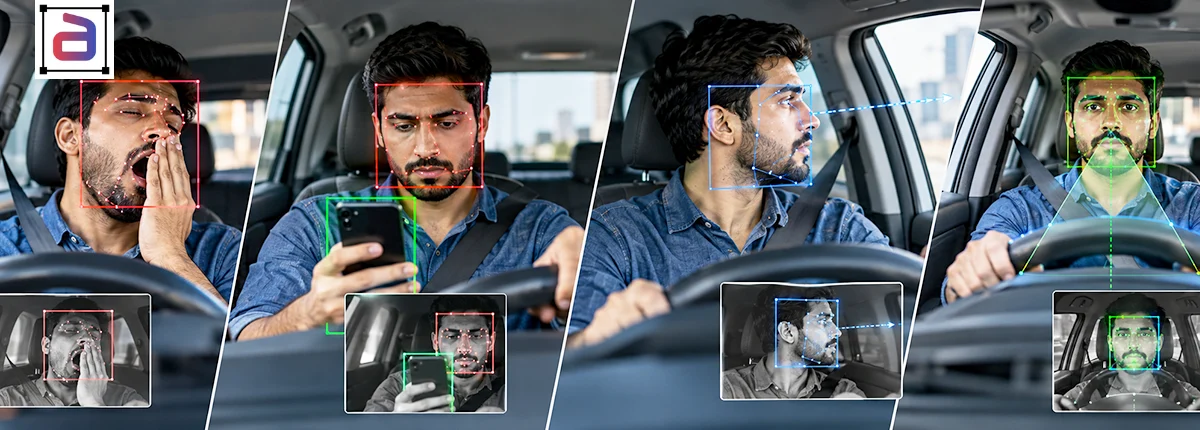
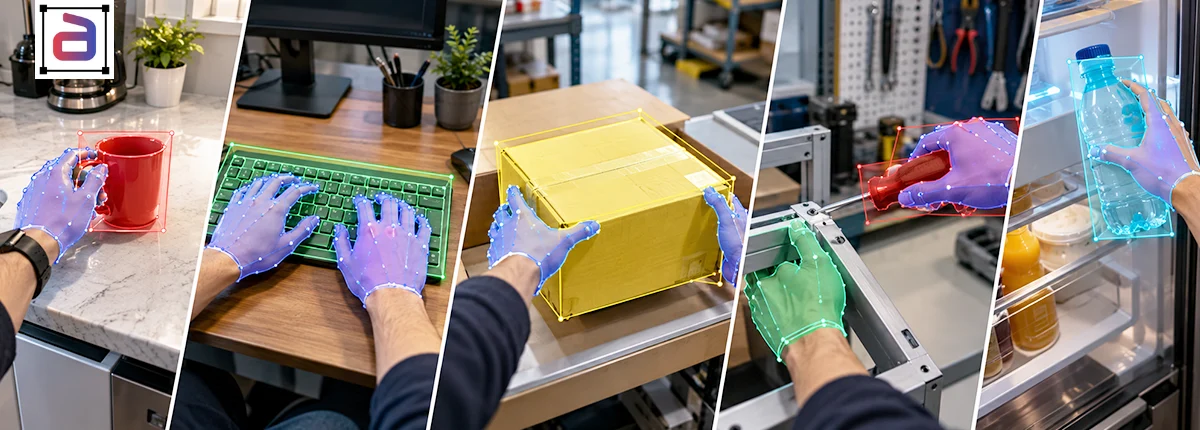
Body, hand and face points labeled frame by frame for pose estimation and motion analysis.

Lanes, road edges and paths traced as connected lines through every frame of a drive.

Start and end points of actions and incidents marked precisely for activity recognition.

Facial and object landmarks tracked across frames for recognition and expression models.

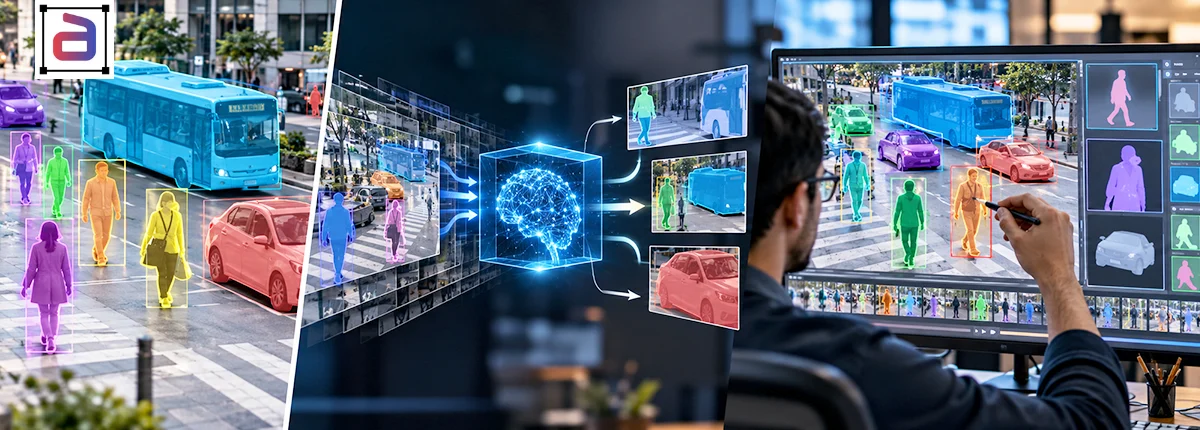
Each tracked object given a class and attributes that stay correct for the whole clip.

Multi Object Tracking

Persistent IDs for every object, so models know who is who through crowds and crossings.

Speech and sound events aligned with on-screen action for multimodal and video-language models.

Occlusion and Visibility Tagging

Hidden, partly visible and re-entering objects tagged consistently for robust tracking.

Frame-by-frame checks that catch drift, ID switches and missed objects before delivery.

Video annotation Services

ProcessHow a Video Annotation Project Works

Every video annotation service we run follows the same sequence, so quality is proven on your own footage before volume arrives.

1. Pilot on Your Clips

We label a sample of your footage, usually within 48 hours, and score it against your gold set and acceptance criteria.

2. Calibrate the Rules

Identity, occlusion and event-boundary rules are written down and agreed, so every annotator handles them the same way.

3. Produce, Measure, Scale

Batches ship with per-class accuracy, ID-switch and event-timing reports, and the team grows with your footage volume.

Why AnnoteraWhy Teams Choose Annotera as a Video Annotation Company

A video labeling service is only as good as its consistency across thousands of frames, and that depends on process, people and security. These are the commitments behind every Annotera video program. Teams that want a fully managed operation can use our data annotation outsourcing services.

Three-Layer QA

Annotator self-review, team-lead checks and independent QA, scored against gold sets with tracking and timing metrics.

Consistency Across Frames

Written rules for identity, occlusion and re-entry keep labels stable through every second of footage.

Certified Security

Operations certified to ISO/IEC 27001:2022, SOC 2 Type II, HITRUST CSF and PCI DSS 4.0.1, with HIPAA-compliant workflows.

Your Tools or Ours

We work in your video annotation platform or established tools, using interpolation and pre-labeling where they help.

Domain-Trained Teams

Dedicated annotators trained on your domain, from driving scenes to store cameras, so expertise builds over time.

Elastic Capacity

Teams scale with your footage volume, drawing on Fusion CX’s 17,000 people across 40 delivery centers in 13 countries.
Connect with an Expert

    FAQQuestions About Our Video Annotation Services

    Answers on techniques, quality metrics, pricing, tools, security and how to get started.

    Video annotation services label objects, people, actions and events across the frames of a video so computer vision models can learn motion and behavior. A managed provider such as Annotera supplies trained annotators, written rules for tracking and occlusion, quality assurance and reporting.

    Frame-by-frame labeling annotates every frame individually. Interpolation labels keyframes and lets the tool fill the frames between, with annotators correcting any drift. Most programs combine both: interpolation for steady motion, frame-by-frame for fast movement, occlusion and close interactions.

    Against a gold set labeled by senior annotators. We report accuracy per class, box and mask overlap (IoU), ID switches and track continuity for tracking work, and event start and end timing against an agreed tolerance.

    Pricing depends on frame rate, object density, the technique and quality targets. Programs are usually priced per minute of footage, per frame, per tracked object or per dedicated annotator. A pilot on your own clips gives an accurate quote before you commit.

    Yes. We work in your in-house or commercial video annotation platform, or provide established tools if you do not have one, and deliver labels in the formats your training pipeline expects.

    Work runs inside Fusion CX operations certified to ISO/IEC 27001:2022, SOC 2 Type II, HITRUST CSF and PCI DSS 4.0.1, with HIPAA-compliant workflows and role-based access. We work only with the footage you provide and never resell datasets.

    Tracking and timing metrics as well as accuracy, written rules for identity and occlusion, annotators trained on your domain, certified security and a pilot on your own footage before you sign.

    A pilot on a sample of your clips is usually delivered within 48 hours of receiving the footage and guidelines. Production ramp time depends on volume and complexity and is agreed during the pilot.

    Get A Quote