Instruction-response pairs, multi-turn dialogues and expert answers that teach your model the behavior you want. Start with a free 48-hour pilot on your own use case.
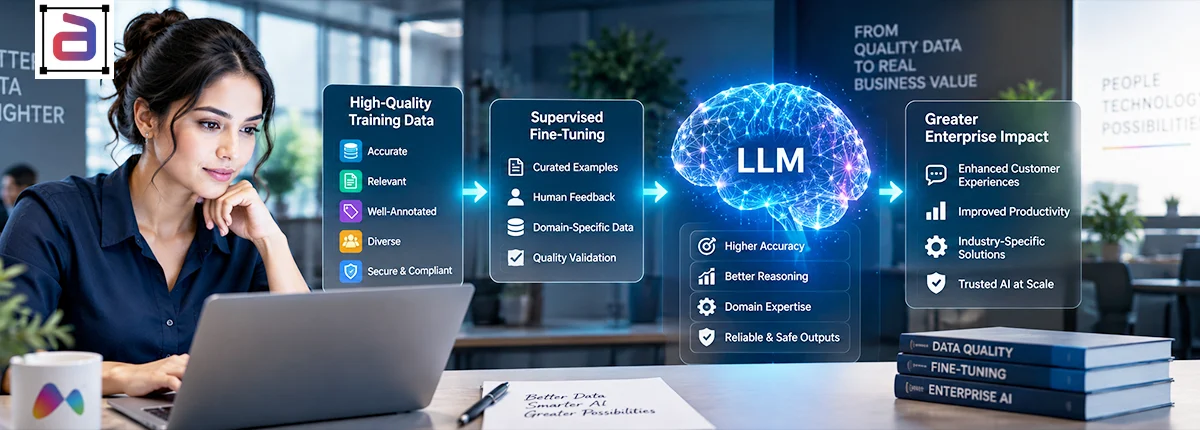
Supervised fine-tuning teaches a language model how to respond by showing it examples of ideal answers. The quality of those examples sets the ceiling on what the model can learn, which is why Annotera’s supervised fine-tuning data services focus on writers who know the domain, rubrics that define a good answer and review that catches errors before they become model behavior.
We create SFT datasets from scratch, extend and clean existing ones, and prepare the data your LLM fine-tuning runs need in the format your pipeline expects. Programs often continue into preference data through our RLHF annotation services and into post-training LLM evaluation services. For background, our guide to supervised fine-tuning data quality explains why quality matters more than volume.
Each dataset is built to a written specification covering tasks, style, length, sources and what the model must not do.

Prompts paired with ideal answers across the tasks your model must handle, written to your style guide.

Realistic conversations that teach context, follow-up, clarification and hand-offs.

Answers written or verified by people with healthcare, legal, finance or technical backgrounds.

Worked solutions that show the steps to an answer, for math, analysis and multi-step tasks.
Code tasks with correct, secure and well-explained solutions, reviewed by technical annotators.
Native-speaker examples in 28+ languages, written for each language, not translated.
Examples that teach the model when and how to decline, warn or redirect, in line with your policy.
Audits of existing SFT sets that find and fix errors, duplicates, inconsistent style and gaps.

Fine-tuning data is only as good as the people who write it. Each program is staffed to match the knowledge your model needs.

Writers with subject-matter backgrounds draft and check answers where accuracy depends on expertise.

Examples in each language are written by native speakers who know its tone, idioms and conventions.

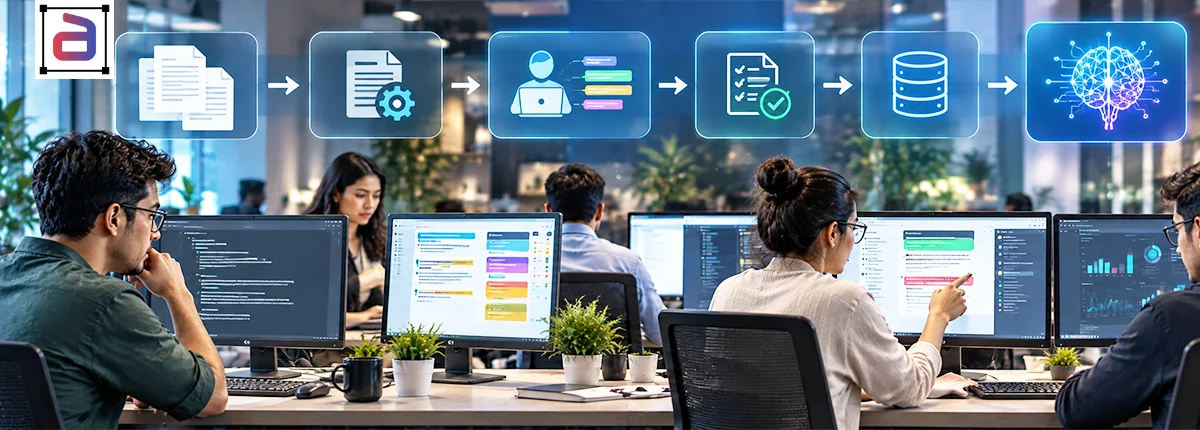
Every example is checked against the rubric for accuracy, completeness, style and safety before delivery.

A structured start makes sure the dataset teaches the behavior you want before volume arrives.

We agree tasks, style, sources and red lines with your team and turn them into a written rubric with examples.

Writers produce a pilot set, usually within 48 hours, which your team reviews before the rubric is finalized.

Batches ship with review scores and issue logs, and the writer pool grows with your volume.
Teams use Annotera when they need fine-tuning data that is expert, consistent and secure, with a partner that can grow with the program.

Writers recruited and trained for your domain, so answers reflect real expertise rather than generic text.

Every example is scored against a written rubric, with senior review and agreement checks on every batch.

Examples are written for your program and never reused or resold to other clients.

Operations certified to ISO/IEC 27001:2022, SOC 2 Type II, HITRUST CSF and PCI DSS 4.0.1, with annotator NDAs.

Delivered in the schema your fine-tuning pipeline expects, with metadata for filtering and versioning.

Writer pools scale with your program, drawing on Fusion CX’s 17,000 people across 40 delivery centers in 13 countries.
Answers on SFT data, quality, volume, formats and getting started.
They create the example data used to fine-tune a language model: prompts paired with ideal responses, multi-turn dialogues and expert answers, written to a rubric and reviewed for accuracy. Annotera supplies the writers, reviewers, rubrics and QA.
Our focus is the data. We create, review and clean the datasets your team or platform uses for fine-tuning, and we can evaluate the results afterwards. Training runs stay with your team.
It depends on the tasks and how far the model must move from its current behavior. Smaller sets of expert, consistent examples often outperform larger generic ones, and a pilot shows where more data helps.
Writers work from a rubric with worked examples, domain experts check specialist content, senior reviewers sample every batch, and recurring issues are logged and fed back into the rubric.
Yes. Native-speaker writers create examples in 28+ languages, written for each language rather than translated, so tone and conventions are right.
SFT data shows the model ideal answers to learn from; RLHF data compares answers the model already gives so it learns which is better. Most programs use both, which our RLHF annotation services cover.
Work runs in certified operations with role-based access, annotator NDAs and secure environments. Examples written for you are never reused or resold.
A pilot set is usually delivered within 48 hours of agreeing the rubric. Production ramp time depends on domain, languages and volume and is agreed during the pilot.