Large language models can process billions of tokens, but scale alone does not guarantee useful, reliable, or production-ready AI behavior. The difference between an impressive prototype and a dependable enterprise LLM often comes down to something less visible: the quality of the data used to train, fine-tune, evaluate, and align the model. Raw prompts are only the beginning. A prompt-response pair becomes genuinely valuable when it is enriched with structured labels, quality judgments, preferences, safety signals, domain context, and human feedback. This transformation requires a carefully engineered annotation pipeline capable of converting messy real-world interactions into consistent, model-ready datasets. As OpenAI’s InstructGPT research demonstrated, human demonstrations and rankings of model outputs can be used to fine-tune models toward better instruction following.
“Making language models bigger does not inherently make them better at following a user’s intent.” — OpenAI, Training language models to follow instructions with human feedback
For AI companies building the next generation of LLMs and GenAI applications, the question is no longer whether annotation is necessary. It is how to design an annotation pipeline that consistently produces high-value training data at scale.
Key Points
- Transform Raw Prompts into Structured Training Data – A well-designed LLM annotation pipeline enriches raw prompts with intent, response quality, safety, factuality, and instruction-following labels.
- Use Human Feedback for Better Model Alignment – Preference ranking and human evaluation create valuable RLHF & fine-tuning data that helps models produce more accurate, relevant, and useful responses.
- Prioritize Domain Expertise and Quality Assurance – Specialized annotation guidelines, expert review, inter-annotator agreement, and multi-level QA improve dataset consistency and reliability.
- Continuously Improve Through Production Feedback – Monitoring real-world model failures and feeding them back into the annotation workflow creates a continuous cycle of dataset and model improvement.
What Makes Raw Prompt Data Insufficient?
Consider a simple prompt: “Summarize this financial report for an executive audience.” A raw prompt provides an instruction, but it does not tell the model what constitutes a good answer. Should the summary prioritize revenue? Risks? Market trends? Should it be 100 words or 500? Should unsupported claims be penalized? What happens if the source document contains contradictory information? A production-grade dataset needs these distinctions captured through annotation. Depending on the application, annotation may include:
- Intent and task classification
- Prompt difficulty labeling
- Response quality scoring
- Preference ranking
- Factuality assessment
- Hallucination identification
- Safety and toxicity labeling
- Instruction-following evaluation
- Domain-specific terminology annotation
- Style and tone classification
The objective is to turn unstructured interactions into structured learning signals that a model can use.
Step 1: Define the Annotation Objective
An effective pipeline starts with the model objective—not the annotation tool. An organization developing a customer-service LLM may prioritize helpfulness, accuracy, empathy, and policy compliance. A coding model may require annotations for functional correctness, security vulnerabilities, reasoning quality, and adherence to programming instructions. Before collecting labels, teams should establish:
- What behavior should the model learn?
- What types of prompts matter most?
- What constitutes an acceptable response?
- Which errors are critical?
- Which labels are subjective?
- How should ambiguous cases be handled?
Detailed annotation guidelines are essential because inconsistent instructions can introduce noise into the dataset.
Step 2: Clean, Filter, and Classify Prompts
Real-world prompt repositories rarely arrive in perfect condition. They may contain duplicate prompts, incomplete instructions, irrelevant queries, personally identifiable information, unsafe content, or examples that have little value for the target model. Preprocessing should therefore include deduplication, privacy filtering, normalization, and quality screening. Prompts can then be categorized by:
- Intent
- Topic
- Domain
- Language
- Task type
- Complexity
- Safety sensitivity
- Expected response format
This classification enables teams to construct balanced datasets rather than allowing the most common prompt types to dominate training.
Step 3: Generate and Evaluate Candidate Responses
The next stage is response annotation. For each prompt, teams can collect human-written responses, model-generated responses, or multiple candidate outputs. Annotators then evaluate them against predefined criteria. Typical evaluation dimensions include:
- Relevance: Does the response address the actual request?
- Accuracy: Are the claims correct and supported?
- Completeness: Does it provide the information necessary to satisfy the task?
- Clarity: Is the response understandable and logically organized?
- Safety: Does it avoid harmful or inappropriate content?
- Instruction adherence: Did the model follow the requested constraints?
This layer transforms a basic prompt-response dataset into a dataset capable of teaching the model what high-quality behavior looks like.
Step 4: Build RLHF & Fine-Tuning Data
One of the most valuable components of an LLM annotation pipeline is preference data. Instead of asking an annotator whether one response is simply “correct,” teams can present multiple outputs and ask which response better satisfies the task. For example:
- Response A: Accurate but overly verbose.
- Response B: Accurate, concise, and directly aligned with the instruction.
- Response C: Well-written but contains an unsupported claim.
A preference label can establish that Response B is preferable for the intended use case. This is the foundation of high-quality RLHF & fine-tuning data. OpenAI has described a similar process for InstructGPT: human-written demonstrations were used for supervised fine-tuning, followed by human rankings of model outputs to train a reward model and further optimize the model.
“Fine-tuning language models with humans in the loop is a powerful tool for improving their safety and reliability.” — OpenAI
The key takeaway is important: human feedback needs to be structured carefully to become useful training data.
Step 5: Add Domain-Specific Annotation
Generic annotation frameworks cannot adequately address every enterprise use case. Legal, financial, healthcare, insurance, retail, and technical applications require specialized taxonomies and evaluation criteria. For example, legal LLM datasets may require clause classification, legal entity identification, citation verification, and jurisdiction-specific context. Financial datasets may require financial terminology, risk classification, numerical accuracy, and regulatory considerations. This is where specialized LLM & GenAI annotation services can provide substantial value. Annotators with appropriate domain expertise can evaluate nuances that automated systems may overlook, helping organizations create datasets aligned with real-world application requirements.
Step 6: Implement Multi-Layer Quality Assurance
High-volume annotation without rigorous QA can create large quantities of low-value data. A mature pipeline should include multiple quality-control mechanisms:
- Annotator qualification tests
- Gold-standard examples
- Double annotation
- Inter-annotator agreement measurement
- Expert adjudication
- Random sampling
- Automated validation
- Error categorization
- Continuous guideline refinement
Disagreement should not automatically be treated as annotation failure. It can reveal ambiguous instructions, overlapping labels, or genuinely difficult examples. Analyzing these disagreements allows teams to improve both the taxonomy and annotation guidelines.
Step 7: Create Dataset Governance and Version Control
Production-ready data also needs traceability. Teams should be able to determine where an example came from, which guidelines were used, who reviewed it, whether it passed QA, and which dataset version contains it. Important metadata can include:
- Source prompt
- Annotation category
- Annotator/reviewer
- Guideline version
- QA status
- Correction history
- Dataset version
- Approval status
Strong governance makes it easier to reproduce experiments and identify which data changes influenced model performance.
Step 8: Close the Loop With Production Feedback
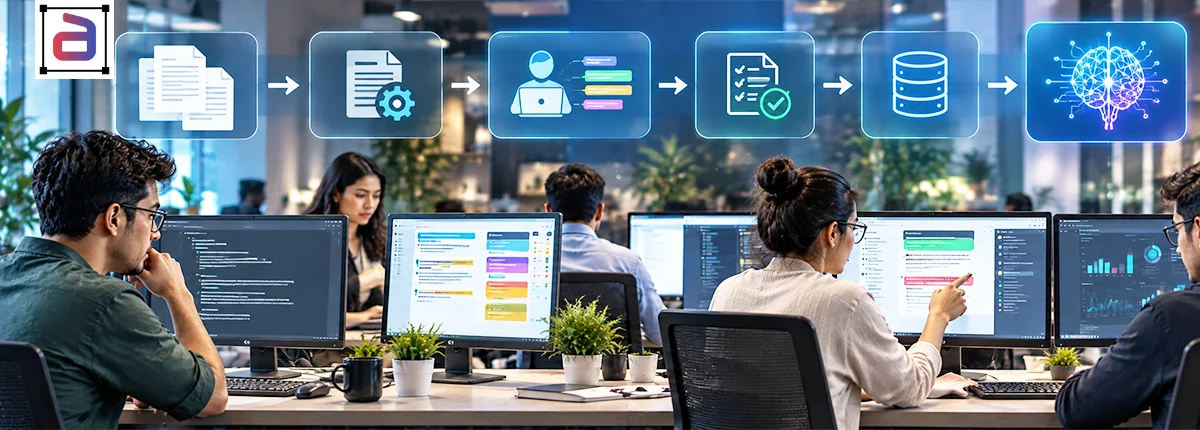
The annotation pipeline should not stop when the dataset is delivered. Once an LLM enters production, real-world interactions expose new failure modes. These failures can become new annotation candidates. The cycle becomes: Production interaction → Failure detection → Prompt selection → Annotation → QA → Dataset update → Model improvement → Re-evaluation This continuous approach enables AI teams to prioritize difficult and high-impact examples rather than endlessly labeling random data.
Why Human Expertise Still Matters
Automation can accelerate preprocessing, deduplication, classification, and quality checks. But nuanced judgments about intent, factuality, preference, safety, and domain context still require carefully designed human-in-the-loop workflows. Research on RLHF has repeatedly demonstrated the value—and limitations—of human preference data. Human judgments can improve model behavior, but the resulting models also reflect the criteria and instructions given to annotators. That makes annotation design just as important as annotation volume.
Build Production-Ready LLM Data With Annotera
At Annotera, we approach LLM data annotation as a structured data-engineering and quality-management process—not simply a labeling task. Our LLM & GenAI annotation services can support prompt classification, response evaluation, preference ranking, safety annotation, instruction-following assessment, domain-specific labeling, and other human-in-the-loop workflows. Whether you are preparing supervised fine-tuning datasets, developing preference datasets, improving model evaluations, or building RLHF & fine-tuning data, Annotera helps transform raw model interactions into structured, high-quality training assets. The future of reliable GenAI will not be determined by model size alone. It will also depend on how effectively organizations transform human expertise into scalable training signals. Ready to turn raw prompts into production-ready training data? Partner with Annotera to build an LLM annotation pipeline designed for quality, consistency, domain expertise, and scale.