Natural Language Processing (NLP) is transforming how businesses interact with information. From intelligent chatbots and virtual assistants to automated document processing and enterprise search, modern AI applications depend on their ability to understand and interpret human language accurately. However, behind every high-performing NLP model is a well-structured, accurately annotated dataset.
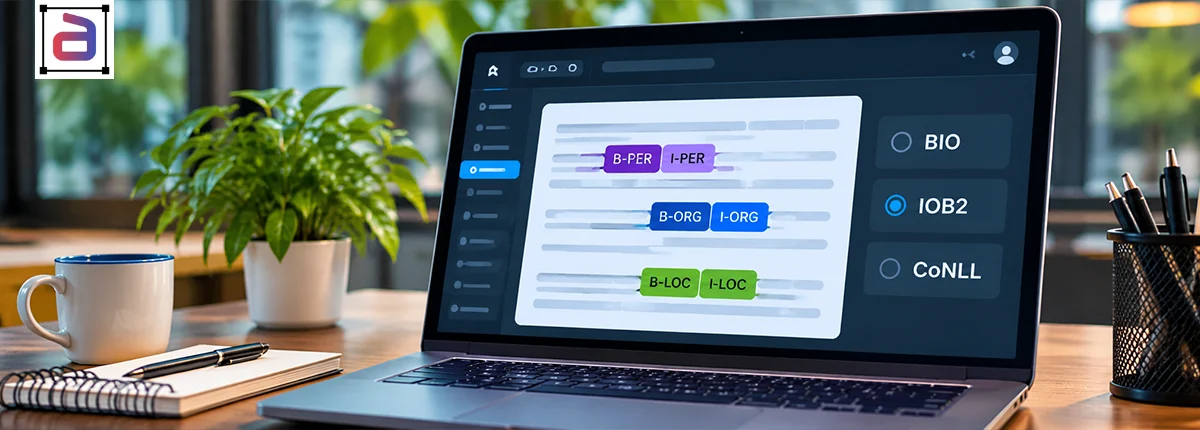
One important aspect of preparing NLP training data is choosing the right annotation format. BIO, IOB2, and CoNLL are widely used approaches for organizing token-level labels, particularly in Named Entity Recognition (NER) and other sequence labeling tasks. Although these formats are closely related, they serve different purposes within the annotation pipeline. Understanding their differences helps AI teams build consistent datasets, minimize labeling errors, and improve model performance. At Annotera, we recognize that annotation consistency is fundamental to reliable AI development. Let’s explore how these formats work and why they matter for NLP applications.
Key Points
- BIO Tagging: Uses Beginning, Inside, and Outside labels to identify entity boundaries and classify text tokens in NLP datasets.
- IOB2 Annotation: Ensures every new entity starts with a B-tag, providing consistent entity boundary identification, particularly in NER tasks.
- CoNLL Format: Organizes token-level annotations into a structured, machine-readable format, supporting NLP model training, evaluation, and data exchange.
- Quality Matters: Accurate annotation guidelines, consistent labeling, and quality assurance are essential for building reliable NLP training datasets. Annotera supports businesses with scalable text annotation outsourcing services.
1. Understanding BIO Tagging in NLP
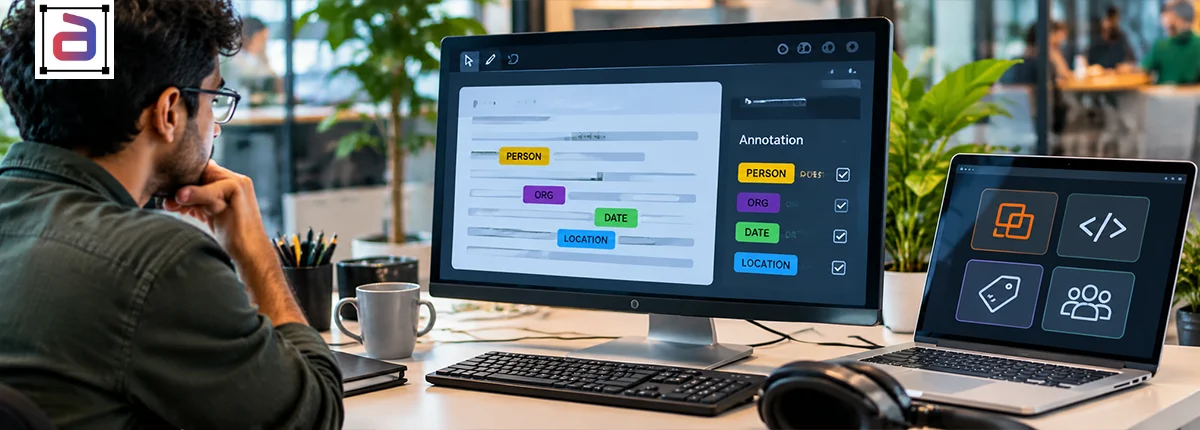
BIO stands for Beginning, Inside, and Outside. It is a popular sequence labeling scheme used to identify specific entities within a sentence. Each word or token receives a label based on its relationship with an entity:
- B (Beginning): Identifies the first token of an entity.
- I (Inside): Identifies subsequent tokens belonging to the same entity.
- O (Outside): Identifies tokens that are not part of any entity.
Consider the sentence: Microsoft opened a new office in New York.
| Token | BIO Tag |
|---|---|
| Microsoft | B-ORG |
| opened | O |
| a | O |
| new | O |
| office | O |
| in | O |
| New | B-LOC |
| York | I-LOC |
In this example, Microsoft is identified as an organization, while New York is recognized as a multi-word location entity.
Why Is BIO Important? BIO tagging helps NLP models understand where an entity starts, which tokens belong to it, and where the entity ends. This is particularly valuable when training models for:
- Named Entity Recognition (NER).
- Information extraction.
- Document processing.
- Customer data identification.
- Automated text classification.
As NLP applications become more sophisticated, consistent BIO labeling helps establish a reliable foundation for model training.
2. What Is IOB2? Understanding Its Tagging Rules
IOB2 is a specific variation of the BIO tagging scheme. It follows the same Beginning, Inside, and Outside principles but introduces a stricter rule for identifying entity boundaries. Under IOB2, every new entity must begin with a B-tag, regardless of whether another entity appears immediately before it. For example: Google hired John Smith.
| Token | IOB2 Tag |
|---|---|
| B-ORG | |
| hired | O |
| John | B-PER |
| Smith | I-PER |
The distinction becomes particularly important when two entities of the same category appear consecutively. Consider: John Smith met Mary Jones. Under IOB2:
| Token | IOB2 Tag |
|---|---|
| John | B-PER |
| Smith | I-PER |
| Mary | B-PER |
| Jones | I-PER |
Each person’s name starts with a B-tag, making the entity boundaries explicit. IOB1 vs. IOB2: What’s the Difference? IOB1 and IOB2 are often confused, but their tagging rules differ:
- IOB1: Uses B-tags primarily when an entity immediately follows another entity of the same type.
- IOB2: Requires every entity to begin with a B-tag.
IOB2 offers a more consistent representation of entity boundaries, making it a practical choice for many NER annotation workflows. For annotation teams, following these rules consistently is essential. Incorrect boundary labels can introduce noise into training datasets and affect downstream entity recognition performance.
3. CoNLL Format: Structuring Annotated Text Data
CoNLL refers to a family of formats and shared tasks used in computational linguistics. In practical NLP workflows, CoNLL commonly describes a structured, token-per-line representation of annotated text. Unlike BIO and IOB2, which define tagging conventions, CoNLL provides a way to organize linguistic information into machine-readable datasets. A typical CoNLL-style representation includes:
- Individual tokens on separate lines.
- Annotation labels associated with each token.
- Additional columns for linguistic information, depending on the task.
- Blank lines separating individual sentences.
For example:
Microsoft B-ORG
opened O
a O
new O
office O
in O
New B-LOC
York I-LOC
. O
Each row represents a token and its corresponding annotation label. Some CoNLL datasets include additional information, such as part-of-speech tags, syntactic dependencies, and grammatical relationships.
Why Does CoNLL Matter? CoNLL makes annotated datasets easier to organize, exchange, validate, and process. It is widely associated with NLP research, benchmarking, and model development. Most importantly, CoNLL can accommodate different tagging schemes, including BIO and IOB2, depending on the dataset requirements. This distinction matters when preparing training data for different NLP frameworks and machine learning pipelines.
4. BIO vs. IOB2 vs. CoNLL: Key Differences
Although these approaches are interconnected, they have different functions in NLP annotation.
| Feature | BIO | IOB2 | CoNLL |
|---|---|---|---|
| Primary purpose | Entity tagging | Consistent entity boundary tagging | Dataset representation |
| Structure | B, I, O labels | B, I, O labels | Token-based columns |
| Entity beginnings | Identified through B-tags | Every entity starts with B | Depends on tagging scheme |
| Multi-word entities | Supported | Supported | Supported |
| Common application | NER | NER | NLP training and evaluation |
The key takeaway is that BIO and IOB2 define how entities are labeled, while CoNLL determines how token-level annotations are structured and represented. Choosing the right combination depends on the NLP task, model architecture, annotation guidelines, and data-processing requirements.
5. Common Challenges in BIO, IOB2, and CoNLL Annotation
Even standardized annotation formats cannot guarantee dataset quality. In large-scale NLP projects, inconsistencies can emerge when annotation guidelines are unclear or quality assurance is insufficient. Some common challenges include:
- Inconsistent Entity Boundaries: Annotators may disagree about whether an entity includes additional descriptive words, particularly in complex product names and organizational titles.
- Incorrect Tag Assignment: Assigning an I-tag without a valid preceding B-tag can create inconsistent sequences under IOB2 conventions.
- Contextual Ambiguity: The same word can represent different entities depending on context. For example, Apple may refer to a technology company or a fruit.
- Formatting Inconsistencies: Incorrect tokenization, missing sentence separators, and inconsistent column structures can create compatibility issues.
- Limited Quality Validation: Without systematic review, annotation mistakes can become embedded in training datasets and influence model predictions.
As a guiding principle for NLP data preparation:
“A model can only learn reliably when its training data represents information consistently and accurately.”
Addressing these challenges requires trained annotators, detailed labeling instructions, automated validation, and multi-level quality checks.
6. How Annotera Helps Build High-Quality NLP Training Datasets
Selecting an annotation format is only the beginning. The real challenge is maintaining accuracy and consistency across thousands or millions of text records. This is where Annotera helps businesses strengthen their AI development workflows. As a specialized text annotation company, Annotera supports organizations in preparing structured, high-quality datasets for NLP, machine learning, and Generative AI applications. Our text annotation capabilities include:
- Named Entity Recognition (NER): Identifying and classifying people, organizations, locations, products, and other entities.
- Intent Classification: Categorizing user queries to improve chatbot and conversational AI performance.
- Text Categorization: Organizing documents and textual information into predefined categories.
- Sentiment Annotation: Identifying opinions, attitudes, and emotional expressions in text.
- Entity Extraction: Identifying relevant information from unstructured documents and business records.
Through our text annotation outsourcing services, businesses can access scalable annotation support tailored to their project requirements. Our approach emphasizes clear annotation guidelines, consistent labeling conventions, structured data preparation, and quality assurance. Whether your project requires BIO tagging, IOB2 labeling, or CoNLL-formatted datasets, Annotera can help prepare text data aligned with your technical specifications.
“High-quality AI starts with high-quality data. Consistent annotation turns unstructured language into meaningful information that machine learning models can understand.”
7. Conclusion: Choosing the Right Annotation Format for NLP Success
BIO, IOB2, and CoNLL each play an important role in preparing structured datasets for Natural Language Processing. BIO provides a straightforward entity-tagging approach, IOB2 introduces stricter entity boundary rules, and CoNLL offers a structured representation for organizing token-level annotations. Understanding these differences helps businesses establish consistent annotation workflows, reduce labeling errors, and prepare reliable datasets for NLP model development. However, the effectiveness of any annotation format ultimately depends on how accurately and consistently it is implemented.
Build Better NLP Models with Annotera
Are you developing an NER model, intelligent chatbot, document processing solution, or enterprise NLP application? Partner with Annotera for scalable, quality-focused text annotation solutions. Our experienced annotation workflows help transform unstructured text into structured training data that supports your AI development goals.