An AI model can generate a grammatically perfect answer and still get the facts wrong. The difference between a convincing response and a reliable one often comes down to the quality of its training data. For question-answering (QA) systems, understanding a question is only the beginning. Models must identify relevant evidence, interpret context, locate precise answers, and recognize when the available information is insufficient.
This is where question answering dataset annotation becomes essential.
From intelligent virtual assistants and enterprise search platforms to retrieval-augmented generation (RAG) systems and conversational AI, modern applications depend on accurately labeled text to understand and respond to human queries. Annotation techniques such as span labeling, answerability classification, and reading comprehension data preparation help AI models develop these capabilities.
At Annotera, we recognize that reliable AI begins with structured, high-quality data. Through carefully designed text annotation workflows, Annotera helps AI teams prepare datasets that support contextual understanding, answer accuracy, and more dependable model evaluation.
What Is Question Answering Dataset Annotation?
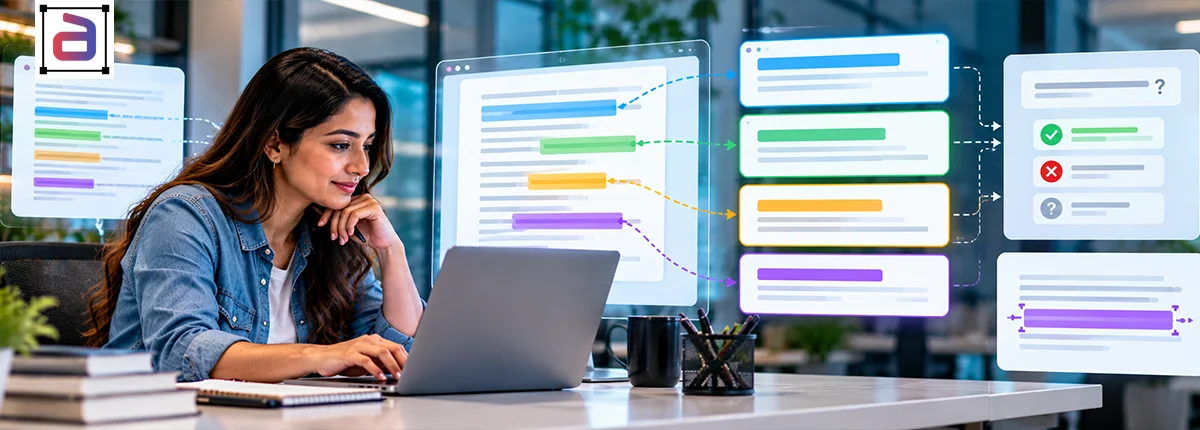
Question answering dataset annotation is the process of labeling questions, supporting passages, answer spans, and contextual relationships to train or evaluate AI models. It establishes connections between a question and the evidence needed to answer it correctly.
Consider the following passage:
“Annotera provides data annotation services for text, images, audio, video, and multimodal AI applications.”
Question: Which types of data annotation services does Annotera provide?
Annotated answer: Text, images, audio, video, and multimodal AI applications.
The annotator identifies the information that directly answers the question and labels the corresponding text according to the project’s annotation guidelines.
However, real-world scenarios are rarely this straightforward. Questions may contain ambiguous references, require information from multiple sentences, or ask for details that are absent from the passage.
High-quality annotation helps models distinguish between explicit evidence, contextual interpretation, and unsupported assumptions.
“Reliable question answering begins with reliable evidence. The better the training data captures the relationship between questions and context, the better equipped a model is to produce grounded responses.”
For AI developers, this means investing in annotation processes that prioritize accuracy, consistency, and contextual relevance.
1. Span Labeling: Teaching AI to Find the Right Answer
Span labeling is a core technique in extractive question answering. It involves identifying the exact portion of a passage that contains the answer to a question.
Rather than generating a response from scratch, an extractive QA model learns to locate the relevant text within the supplied context.
Why Span Labeling Matters
Accurate span labeling enables AI models to:
- Locate relevant information in lengthy documents.
- Identify precise answers instead of returning entire paragraphs.
- Distinguish between similar entities, dates, and numerical values.
- Connect answers to supporting evidence.
- Reduce errors caused by incomplete or inconsistent labels.
For example, consider this passage:
“The organization launched its AI annotation platform in March 2025 to support enterprise data preparation.”
Question: When did the organization launch its AI annotation platform?
Correct answer span: “March 2025”
The annotation must capture the complete answer without including unnecessary information.
Challenges arise when answers contain modifiers, overlapping phrases, multiple candidate entities, or references distributed across sentences. Without standardized guidelines, different annotators may label different portions of the same passage.
Annotera helps address these challenges through structured text annotation workflows that emphasize clearly defined labeling rules and consistent annotation practices.
For AI teams developing document intelligence, knowledge retrieval, and conversational systems, precise span labeling can provide a stronger foundation for extracting information from unstructured text.
2. Answerability Annotation: Helping AI Recognize What It Does Not Know
An intelligent question-answering system should not attempt to answer every question. Sometimes, the available passage simply does not contain enough information to support a reliable response.
Answerability annotation teaches models to distinguish between questions that can be answered using the supplied context and those that cannot.
Understanding Answerability Categories
Depending on the application, annotation guidelines may include the following categories:
- Answerable: The passage contains sufficient evidence to answer the question.
- Unanswerable: The required information is absent from the passage.
- Insufficient context: The available information is incomplete and cannot support a definitive answer.
- Ambiguous: The question or supporting information permits multiple plausible interpretations.
These categories must be defined carefully. Some datasets use a simple answerable-versus-unanswerable classification, while more complex enterprise applications may require additional labels.
Consider this example:
Passage: “The company provides text annotation and image annotation services.”
Question: Does the company provide audio annotation services?
Although the question concerns a related service category, the passage does not establish whether audio annotation is offered. The appropriate annotation should reflect the evidence available rather than assume an answer.
This capability is particularly important for RAG applications, enterprise knowledge assistants, and customer support systems, where unsupported answers can damage user trust.
“A trustworthy AI system must learn not only how to answer correctly, but also when the available evidence does not justify an answer.”
For Annotera, answerability annotation is an important part of building datasets that encourage evidence-based responses and help AI teams evaluate how models handle missing information.
3. Reading Comprehension Annotation: Moving Beyond Keyword Matching
Recognizing individual words does not necessarily mean understanding a passage. Reading comprehension annotation helps AI models learn to interpret context, identify relationships, resolve references, and connect information across sentences.
Consider the following example:
“Priya joined the data annotation team in January. Three months later, she began working on complex natural language processing datasets.”
Question: When did Priya begin working on complex NLP datasets?
To answer correctly, a model must connect the phrase “three months later” with the earlier time reference. Simply matching keywords is not sufficient.
Key Components of Reading Comprehension Annotation
- Contextual understanding: Identifying the passage or sentence that supports an answer.
- Coreference resolution: Determining which person, organization, or object a pronoun or referring expression represents.
- Cross-sentence reasoning: Connecting relevant information distributed across multiple sentences.
- Question-context alignment: Ensuring that the labeled answer follows from the supplied passage.
- Temporal and relational interpretation: Understanding relationships involving dates, sequences, events, and entities when required by the task.
These annotation capabilities support applications such as intelligent document processing, legal document analysis, enterprise search, customer support automation, and knowledge management.
Annotera helps AI teams prepare structured text datasets that reflect the contextual relationships language models need to process real-world information more effectively.
4. Common Challenges in Question Answering Dataset Annotation
Even sophisticated annotation projects face challenges that can introduce noise into training data.
Ambiguous Questions
Questions such as “Which solution is better?” cannot be answered reliably without clear comparison criteria. Annotation guidelines should explain how to handle ambiguity and insufficient context.
Multiple Candidate Answers
A passage may contain several dates, names, or numbers. Annotators must identify the answer supported by the question rather than select the first matching phrase.
Inconsistent Span Boundaries
Different annotators may disagree about whether an answer should include modifiers, titles, or surrounding words. Standardized span-labeling rules and calibration exercises help minimize these discrepancies.
Domain-Specific Terminology
Healthcare, finance, engineering, and legal documents contain specialized vocabulary that requires appropriate contextual guidance. Domain-specific annotation instructions can improve consistency and reduce interpretation errors.
Dataset Bias and Duplication
Repeated questions, duplicated passages, and predictable answer patterns can distort training outcomes and evaluation results. Deduplication, dataset coverage checks, and appropriate training-test separation help address these risks.
The solution is not simply more annotations. It is better-controlled annotation. Clear guidelines, trained annotators, systematic quality checks, and expert adjudication all contribute to more dependable datasets.
5. Best Practices for Building High-Quality QA Datasets
A structured annotation framework helps maintain consistency as datasets grow in size and complexity.
- Define the annotation objective. Determine whether the project requires extractive QA, answerability classification, reading comprehension, or a combination of these tasks.
- Develop comprehensive guidelines. Specify answer-span boundaries, supported evidence, ambiguity handling, and unanswerable question criteria.
- Train and calibrate annotators. Use representative examples, practice exercises, and feedback sessions to align labeling decisions.
- Establish quality assurance procedures. Apply annotation audits, inter-annotator agreement analysis, sampling, and adjudication to identify inconsistencies.
- Validate the completed dataset. Check label accuracy, missing values, duplicate records, answerability distribution, and data leakage between training and evaluation sets.
- Improve iteratively. Analyze model errors and recurring annotation disagreements to refine guidelines and strengthen future datasets.
For organizations managing large-scale AI initiatives, partnering with a specialized text annotation company can provide additional annotation capacity and structured quality management without requiring every activity to be handled internally.
6. Why Choose Annotera for Question Answering Dataset Annotation?
Developing dependable QA systems requires training data that captures how questions relate to evidence. Every answer span, contextual relationship, and answerability label contributes to how a model learns to interpret information.
Annotera supports AI development through specialized data annotation workflows designed to help organizations prepare structured, high-quality text datasets.
Our annotation capabilities can support workflows involving:
- Extractive question answering and precise span labeling.
- Answerability classification and unanswerable question identification.
- Reading comprehension and contextual relevance annotation.
- Entity and reference identification within text.
- Annotation quality checks and consistency reviews.
For organizations seeking to scale their data preparation operations, text annotation outsourcing services can help manage growing annotation requirements, streamline workflows, and provide access to structured quality assurance processes.
Annotera works with project-specific requirements to help align annotation guidelines, labeling structures, and quality checks with the intended AI application.
Whether your team is developing conversational AI, enterprise knowledge assistants, intelligent document processing solutions, or RAG-based systems, a well-designed annotation strategy can help establish a more reliable foundation for model development.
Conclusion
Question answering dataset annotation is fundamental to developing AI systems that can locate accurate answers, understand context, and recognize the limits of available evidence.
Span labeling teaches models where answers are found. Answerability annotation helps them determine whether a question can be answered from the supplied context. Reading comprehension annotation strengthens their ability to interpret relationships and derive meaning from text.
Together, these techniques help AI teams build datasets that support more reliable training, meaningful evaluation, and evidence-based question answering.
As language models become increasingly integrated into business operations, organizations must prioritize annotation quality alongside model architecture and computational resources.
Annotera helps AI teams turn unstructured text into structured training data designed for more dependable AI performance.
Ready to Strengthen Your Question-Answering AI?
Build a stronger foundation for your next AI project with Annotera. Explore our text annotation outsourcing services to prepare high-quality question-answering datasets, improve contextual labeling consistency, and support your model training and evaluation goals.
Contact Annotera today to discuss your question answering dataset annotation requirements and discover an approach tailored to your AI development needs.