In a digital environment where information travels faster than ever, distinguishing facts from misinformation has become a critical challenge. Social media platforms, online publishers, and AI-powered applications process enormous volumes of textual information every day. However, identifying whether a statement is accurate, misleading, or unsupported requires more than simply analyzing words. It demands contextual understanding, credible evidence, and systematic verification.
As large language models (LLMs) become increasingly integrated into search engines, virtual assistants, and content moderation systems, the quality of their training data plays a decisive role in how effectively they evaluate factual claims. This is where fact-checking and claim verification annotation becomes indispensable. By transforming unstructured information into carefully labeled, evidence-backed datasets, annotation enables AI models to learn the difference between verified facts, contradictory evidence, and claims that remain uncertain. At Annotera, we recognize that trustworthy AI begins with trustworthy data. Building reliable misinformation detection systems requires structured annotation workflows that prioritize factual accuracy, contextual relevance, and consistent quality standards.
Key Points
- Evidence-Based Verification: Fact-checking annotation helps AI models distinguish supported, refuted, misleading, and unverified claims using credible evidence and contextual analysis.
- Structured Annotation Workflows: Claim extraction, evidence collection, label assignment, and human review improve dataset accuracy and consistency.
- Challenges in Misinformation Detection: Addressing conflicting sources, evolving information, multilingual content, and annotation bias is essential for building reliable AI datasets.
- Annotera’s Text Annotation Expertise: Annotera supports AI development with quality-focused text annotation solutions that help organizations build structured datasets for misinformation detection and factual verification.
What Is Fact-Checking and Claim Verification Annotation?
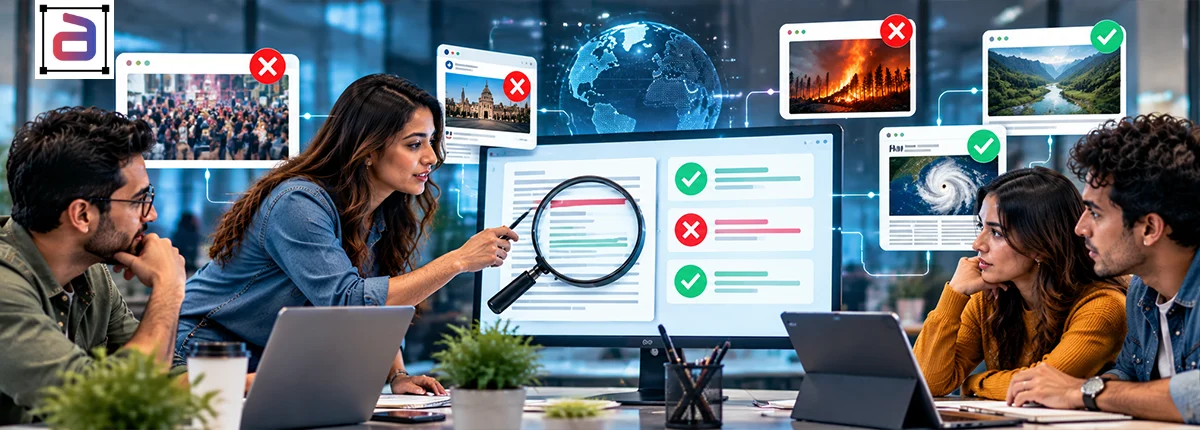
Fact-checking and claim verification annotation is the process of identifying factual claims, examining supporting evidence, and assigning labels that describe the relationship between a claim and the available information. Unlike conventional text classification, this process requires annotators to evaluate meaning, context, and evidence before reaching a conclusion.
Consider the statement:
“A country’s renewable energy capacity increased by 40% in one year.”
An effective annotation workflow would identify the claim, determine the relevant reporting period, locate credible energy statistics, and compare the reported figures with the original statement.
Depending on the evidence, the claim could be classified as supported, refuted, or insufficiently verified. This distinction matters because an unsupported claim is not automatically false, and a technically accurate statement can still mislead readers when important context is omitted.
As a guiding principle for dataset development: “A reliable fact-checking dataset must teach AI models not only what conclusion to reach, but also which evidence justifies that conclusion.” This principle emphasizes the importance of evidence-linked annotation in developing more dependable misinformation detection systems.
Why High-Quality Annotation Is Essential for Detecting Misinformation
AI models can process vast amounts of text, but their ability to evaluate factual accuracy depends partly on the quality and diversity of their training examples. Poorly labeled datasets can reinforce incorrect associations, confuse factual contradictions with missing evidence, and produce unreliable predictions.
High-quality annotation addresses these challenges in several ways.
1. Improves factual classification Clearly defined labels help models distinguish supported claims from refuted statements and assertions that cannot yet be verified.
2. Strengthens evidence-based reasoning Connecting claims to relevant passages helps models learn how supporting information relates to a conclusion rather than relying exclusively on linguistic patterns.
3. Reduces contextual errors Annotation guidelines encourage reviewers to consider dates, locations, qualifications, and surrounding statements before assigning labels.
4. Supports explainable AI Evidence-linked datasets provide a foundation for systems that can identify the sources or passages underlying their conclusions, making their outputs easier to inspect and evaluate.
5. Improves adaptability Datasets containing different writing styles, languages, subject areas, and claim structures help developers evaluate how models perform across varied real-world scenarios.
For AI organizations, these benefits make annotation a strategic component of developing reliable fact-checking and content verification applications.
Essential Labels for Claim Verification Datasets
A successful annotation project begins with a clearly defined label taxonomy. Although the exact categories depend on the application, the following labels provide a useful starting point.
- Supported: Credible evidence sufficiently supports the claim.
- Refuted: Reliable evidence contradicts the claim.
- Insufficient evidence: Available information does not establish whether the claim is accurate.
- Misleading: The statement contains accurate elements but omits essential context or presents information in a way that creates a false impression.
- Unverifiable: The claim cannot be reliably assessed using the available evidence or the project’s verification criteria.
These categories must be accompanied by explicit definitions and examples. Otherwise, two annotators may interpret the same statement differently. For instance, a claim about a recently announced government policy might initially receive an insufficient-evidence label because authoritative documentation is unavailable. If an official announcement later confirms the details, the claim may require reassessment. “Uncertainty is not a labeling failure; it is information that a well-designed dataset must preserve.” Recognizing uncertainty helps prevent AI models from treating every factual question as though a definitive answer is always available.
The Fact-Checking Annotation Workflow
Developing reliable datasets requires a repeatable workflow that combines human judgment, evidence collection, and quality assurance.
Step 1: Identify and Extract Verifiable Claims
Annotators examine articles, social media posts, online discussions, and other textual sources to identify statements that can be checked against evidence. Complex sentences may contain multiple factual assertions. Separating them into individual claims allows each assertion to be evaluated independently. For example, a statement about a new medical treatment might include claims about its approval status, effectiveness, and safety. Each component requires separate verification.
Step 2: Collect Credible Supporting Evidence
Annotators identify relevant sources, including government publications, scientific research, institutional reports, official datasets, and reputable news organizations. Evidence assessment should consider source credibility, publication date, relevance, and authenticity. The presence of a claim on a widely shared website does not establish its accuracy. For time-sensitive topics, recording when the evidence was published and accessed can also help maintain dataset traceability.
Step 3: Compare Claims Against Evidence
Once the evidence is collected, annotators determine whether it supports, contradicts, or fails to resolve the claim. They must consider qualifiers, numerical details, temporal context, and the possibility that multiple sources present different findings. Clear decision rules help maintain consistency, especially when evidence is incomplete or conflicting.
Step 4: Link Claims to Relevant Evidence
Evidence-linked annotation connects each claim to the passages or documents that support its assigned label. These relationships are valuable for training retrieval-augmented generation systems, fact-checking applications, and language models designed to produce evidence-grounded responses.
Step 5: Conduct Human Review and Quality Assurance
Independent reviews, adjudication, and agreement measurements help identify inconsistent labels and ambiguous guidelines. Difficult claims should be escalated to experienced reviewers or subject-matter specialists when necessary. Feedback from these reviews can then be incorporated into updated annotation instructions. This structured approach helps ensure that the final dataset is consistent, traceable, and suitable for model development.
Major Challenges in Misinformation Annotation
Despite its importance, fact-checking annotation presents several challenges that AI developers must address. Context-dependent claims: Statements may be accurate in isolation but misleading without relevant background information. Annotators must evaluate the surrounding context before assigning a label. Conflicting sources: Different publications may report different findings because of methodological differences, incomplete data, or changing circumstances. Annotation guidelines should define how conflicting evidence is documented and resolved. Evolving information: Claims about elections, public health, financial markets, and policy changes may become outdated. Time-stamped evidence and periodic dataset reviews help maintain relevance. Multilingual misinformation: Claims expressed through regional terminology, sarcasm, idioms, or culturally specific references can be difficult to interpret. Linguistically capable annotators and localized guidelines can improve accuracy. Annotation bias: Inconsistent source selection or subjective interpretation can influence labeling outcomes. Standardized procedures, independent reviews, and diverse evaluation samples help identify potential biases. Addressing these challenges requires more than increasing annotation volume. It demands a disciplined approach to evidence evaluation and quality management.
How Text Annotation Outsourcing Services Help AI Teams
Building a comprehensive fact-checking dataset requires trained annotators, detailed guidelines, quality assurance procedures, and the ability to process large volumes of diverse textual information. For organizations developing AI systems, managing these requirements internally can consume significant time and resources. Partnering with a specialized text annotation company can help streamline dataset development while maintaining consistent annotation standards. Professional text annotation outsourcing services can support:
- Claim extraction and factual statement identification.
- Classification of supported, refuted, and insufficiently verified claims.
- Evidence-to-claim linking and source attribution.
- Multilingual text annotation and contextual review.
- Quality assurance, adjudication, and annotation consistency checks.
- Structured dataset preparation for AI training, validation, and evaluation.
At Annotera, we understand that effective AI training data must reflect the complexity of real-world information. Our text annotation capabilities can support organizations developing fact-checking applications, misinformation detection models, content moderation systems, and evidence-based language processing solutions. By emphasizing structured workflows, clear labeling criteria, and quality-focused review, Annotera helps AI teams build datasets aligned with their specific model development requirements. The objective is straightforward: create data that supports more consistent, evidence-aware AI performance.
Best Practices for Building Reliable Fact-Checking Datasets
Organizations can strengthen their annotation programs by adopting several best practices.
- Develop detailed annotation guidelines: Define each label, document edge cases, and provide representative examples.
- Maintain evidence traceability: Record source references, relevant passages, publication dates, and verification timestamps where appropriate.
- Include challenging examples: Incorporate ambiguous, partially supported, contradictory, and context-dependent claims rather than relying only on straightforward cases.
- Measure annotation consistency: Use independent reviews and appropriate agreement metrics to identify systematic disagreements.
- Prevent data leakage: Keep training, validation, and test datasets appropriately separated, including checks for duplicated or near-duplicated claims.
- Review datasets periodically: Reassess time-sensitive claims when new evidence becomes available and maintain version histories for updated annotations.
- Evaluate model performance carefully: Measure classification quality across different claim types, languages, and subject areas rather than relying on a single overall accuracy score.
These practices help organizations develop datasets that better represent real-world verification challenges.
Conclusion: Build More Trustworthy AI With High-Quality Annotation
Misinformation detection depends on the ability to distinguish verified facts from unsupported assertions, contradictory evidence, and misleading interpretations. Achieving this requires more than collecting text. It demands carefully extracted claims, credible sources, consistent labels, and rigorous quality assurance. Fact-checking and claim verification annotation provides the structured foundation AI systems need to evaluate information more responsibly. When evidence is linked to claims and uncertainty is represented accurately, datasets become more useful for developing and evaluating fact-checking models. For organizations working toward more reliable AI applications, investing in annotation quality is an important step toward improving factual classification and evidence-based reasoning. Annotera helps AI teams transform unstructured text into structured, quality-focused training datasets for advanced language processing applications. Whether you are developing misinformation detection models, automated fact-checking tools, or evidence-grounded conversational AI, the right annotation partner can help you establish a stronger data foundation.
Ready to Build More Reliable AI Training Data?
Partner with Annotera to explore scalable text annotation solutions tailored to your AI development goals. Connect with our team to discuss your dataset requirements and discover how structured, quality-focused annotation can support your next AI initiative. Visit Annotera to get started with your text annotation project.