Large language models (LLMs) can generate fluent, convincing responses in seconds. But can they distinguish facts from assumptions, identify contradictions, and recognize when available information is insufficient to support a conclusion? These capabilities are essential for building reliable AI systems. Natural Language Inference (NLI) annotation helps evaluate these abilities by identifying the logical relationship between two statements. Through three fundamental labels—entailment, contradiction, and neutrality—AI teams can create structured datasets that test whether language models interpret information accurately and generate evidence-based responses. As organizations increasingly deploy LLMs for customer support, document processing, research, and enterprise decision-making, high-quality text annotation is becoming critical to evaluating model reliability. Annotera helps AI teams develop structured annotation workflows that support the creation of dependable datasets for natural language understanding and LLM evaluation.
Key Points
- Three Core NLI Labels: Natural Language Inference annotation classifies text relationships as entailment, contradiction, or neutrality to evaluate semantic understanding and logical consistency in LLMs.
- Improved LLM Evaluation: NLI datasets help identify factual inconsistencies, detect unsupported claims, and assess whether AI-generated responses remain grounded in source material.
- Quality-Driven Annotation: Clear guidelines, contextual understanding, human review, and rigorous quality assurance are essential for building reliable NLI evaluation datasets.
- Scalable Annotation With Annotera: Annotera supports AI teams with structured text annotation workflows designed to strengthen dataset quality and support reliable LLM evaluation.
What Is Natural Language Inference Annotation?
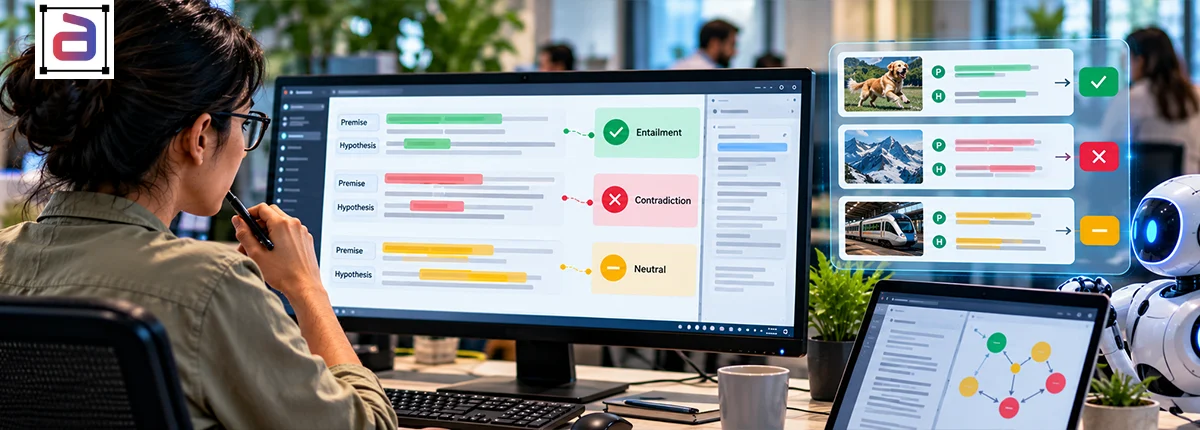
Natural Language Inference is a natural language processing (NLP) task that determines whether a hypothesis is supported, contradicted, or neither supported nor contradicted by a given premise. NLI annotation involves assigning the appropriate label to each premise-hypothesis pair according to predefined guidelines. Consider this example:
- Premise: The company launched its new application in September.
- Hypothesis: The company’s new application was released in September.
- Label: Entailment
Although the wording differs, the hypothesis preserves the meaning of the premise. Now consider a hypothesis stating that the application was released in November. This would contradict the premise. If the hypothesis stated that the application attracted 10,000 users, the relationship would be neutral because the premise provides no information about user adoption. These distinctions may appear straightforward, but real-world language introduces ambiguity, implied meanings, domain-specific terminology, and complex contextual relationships. Accurate NLI annotation requires annotators to interpret meaning rather than simply match keywords.
The Three Core Labels in NLI Annotation
Understanding the three NLI labels is essential for developing reliable evaluation datasets.
1. Entailment: Identifying What the Evidence Supports
Entailment occurs when the hypothesis logically follows from the premise. The statements do not need identical wording, provided the hypothesis introduces no unsupported information. Example:
- Premise: Every employee attending the workshop received a certificate.
- Hypothesis: Workshop attendees received certificates.
- Label: Entailment
The hypothesis is supported by the premise. For LLM evaluation, entailment annotation helps assess whether models preserve meaning when summarizing documents, paraphrasing statements, or answering questions using retrieved information. It is particularly useful in retrieval-augmented generation (RAG), where generated responses should be grounded in source documents rather than assumptions. Annotators must pay attention to details such as quantities, conditions, and qualifications. A hypothesis claiming that every employee received a certificate would not be justified if the premise stated that only some attendees received one.
2. Contradiction: Detecting Inconsistent Claims
Contradiction occurs when the hypothesis conflicts with information established by the premise. Example:
- Premise: The warehouse operates exclusively during daytime hours.
- Hypothesis: The warehouse operates throughout the night.
- Label: Contradiction
The statements describe incompatible operating conditions. Contradiction annotation helps AI teams evaluate whether language models introduce factual inconsistencies, misinterpret source material, or generate responses that conflict with established evidence. This capability is valuable in enterprise search, automated reporting, document analysis, and AI-powered customer service, where conflicting information can undermine user confidence. However, annotators must distinguish genuine contradictions from statements that describe different but compatible circumstances. For example, saying that an employee works remotely does not necessarily contradict a statement that the employee occasionally visits the office.
3. Neutrality: Recognizing What Cannot Be Concluded
Neutrality applies when the premise neither establishes the hypothesis as true nor directly contradicts it. Example:
- Premise: A technology company opened a new office in Bengaluru.
- Hypothesis: The new office employs 200 software engineers.
- Label: Neutral
The premise confirms the office opening but provides no information about its workforce. The hypothesis may be true, but the available evidence does not establish it. Neutrality is especially important for evaluating LLMs because plausible statements are not necessarily evidence-based statements. A model might generate specific details that sound credible but cannot be verified from the supplied context. For AI teams, neutral examples help test whether a model recognizes information gaps instead of presenting unsupported assumptions as established facts.
Why NLI Annotation Matters for LLM Evaluation
Traditional language evaluation often emphasizes relevance, fluency, and task completion. However, a response can satisfy these criteria while still misrepresenting its source material. NLI annotation provides a structured approach to investigating this problem.
- Evaluating factual consistency: Premise-hypothesis pairs help identify whether generated statements agree with, conflict with, or go beyond the available evidence.
- Testing semantic understanding: NLI datasets challenge models to interpret paraphrases, negation, temporal relationships, and contextual meaning.
- Improving RAG evaluation: Comparing generated claims against retrieved passages helps evaluation teams investigate whether responses are grounded in their supporting documents.
- Strengthening benchmark datasets: Carefully designed NLI examples provide repeatable tests for comparing model performance across different linguistic patterns.
- Supporting responsible AI deployment: In healthcare, finance, legal technology, and enterprise applications, recognizing contradictions and unsupported claims can contribute to more dependable AI workflows.
As the computer scientist and linguist Noam Chomsky observed, “Language is a process of free creation.” This perspective highlights an important challenge for generative AI: the ability to produce language does not automatically guarantee that its statements are logically supported. NLI evaluation helps AI teams investigate the distinction between generating convincing text and maintaining consistency with evidence.
Best Practices for Building High-Quality NLI Datasets
Reliable evaluation begins with reliable annotations. AI teams should establish a systematic approach to dataset development.
Develop Precise Annotation Guidelines
Define entailment, contradiction, and neutrality using clear decision rules and representative examples. Include guidance for negation, numerical comparisons, temporal expressions, pronoun references, and ambiguous statements. Annotators should assess the relationship between the premise and hypothesis rather than rely on personal assumptions or outside knowledge.
Incorporate Contextual Understanding
Some statements cannot be interpreted accurately in isolation. Provide sufficient context to resolve references, understand domain-specific language, and distinguish between explicit facts and implied information.
Establish Rigorous Quality Assurance
Use independent annotations, inter-annotator agreement measurements, and expert adjudication to identify inconsistent judgments. Metrics such as Cohen’s kappa can help assess agreement between two annotators while accounting for chance agreement. Recurring disagreements should inform updates to the annotation guidelines.
Include Challenging and Diverse Examples
A useful NLI dataset should cover straightforward cases as well as subtle semantic relationships. Include examples involving negation, paraphrasing, numerical reasoning, temporal references, and partial information. Review the distribution of labels to identify imbalances that could distort evaluation results.
Combine Human Expertise With Automated Validation
Automated tools can identify duplicate examples, missing labels, formatting errors, and certain inconsistencies. However, nuanced semantic relationships often require human interpretation. Combining automated checks with human review helps establish a more dependable quality-control process.
How Annotera Supports Natural Language Inference Annotation
Developing reliable NLI datasets requires consistent labeling, carefully defined taxonomies, and quality-control processes that scale with project requirements. Annotera supports AI teams seeking structured text annotation workflows for natural language understanding, LLM evaluation, and other language-based applications. Through project-specific annotation guidelines, human review, and quality-focused workflows, Annotera helps organizations work toward datasets that reflect their evaluation objectives. These datasets can support the development and assessment of language models across applications such as conversational AI, document intelligence, semantic analysis, and RAG systems. For organizations managing large or specialized datasets, text annotation outsourcing services can provide a practical way to scale annotation operations while allowing internal teams to focus on model development, experimentation, and deployment. Selecting the right text annotation company is equally important. AI teams should prioritize annotation partners that understand complex labeling taxonomies, follow consistent guidelines, address ambiguous examples systematically, and support measurable quality assurance. At Annotera, the focus is on helping AI teams establish annotation workflows aligned with their data requirements and quality expectations. By investing in structured annotation and human oversight, organizations can build a stronger foundation for evaluating language models.
Conclusion: Build More Reliable LLM Evaluation Datasets With Annotera
Natural Language Inference annotation plays a crucial role in evaluating whether AI models understand the relationship between statements. By labeling entailment, contradiction, and neutrality, organizations can investigate factual consistency, semantic understanding, and the ability to distinguish evidence from unsupported conclusions. However, the usefulness of an NLI benchmark depends on the quality of its underlying annotations. Clear guidelines, diverse examples, contextual interpretation, and rigorous quality assurance are essential for producing meaningful evaluation results. As LLM applications continue to expand, investing in dependable text annotation is an important step toward more reliable language AI systems. Ready to strengthen your LLM evaluation pipeline? Partner with Annotera to explore scalable text annotation solutions tailored to your natural language understanding, semantic evaluation, and LLM data requirements. Contact Annotera today to discuss your annotation needs and build a stronger foundation for AI evaluation.
A closely related read: RAG vs. Fine-Tuning: Which One Should You Choose?