PII Redaction and Anonymization in Text Datasets: Balancing Privacy and Model Utility
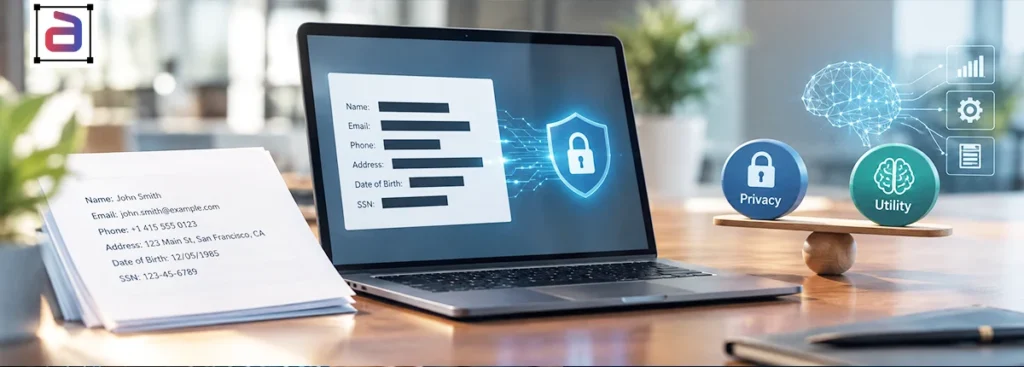
Text datasets are the foundation of many modern AI and NLP systems, but they often contain information that was never intended to become part of a machine learning pipeline. Names, email addresses, phone numbers, financial details, medical information, and other personally identifiable information (PII) can appear naturally within customer conversations, support tickets, legal documents, and […]
Coreference Resolution: Teaching Models to Track Entities Across Long Documents
A document can introduce an entity once and refer to it dozens of times afterward without repeating its name. “Dr. Maya Patel” may become “Dr. Patel,” “the researcher,” “she,” or simply “the scientist” several pages later. Humans usually follow these references effortlessly. For AI systems, however, connecting them correctly is a fundamental natural language understanding […]
Machine Translation Quality Annotation: Human-in-the-Loop Evaluation for MT Pipelines
Machine translation has moved far beyond simple word-for-word conversion. Today, neural machine translation (NMT), large language models (LLMs), and multilingual AI systems can translate millions of words across languages in a fraction of the time required by human teams. But there is a fundamental challenge: fast translation is not necessarily accurate translation. A sentence can […]
Text Summarization Annotation: Evaluating Faithfulness and Coherence in Generated Summaries
The rise of generative AI has transformed how organizations consume information. Instead of manually reading hundreds of pages, users can increasingly rely on AI systems to produce concise summaries of reports, research papers, legal documents, medical records, customer feedback, and business communications. But there is a fundamental question behind every generated summary: Can we trust […]
Relation Extraction: Mapping Structured Knowledge from Unstructured Text
Every organization sits on a growing mountain of unstructured information. Contracts, emails, research papers, financial reports, medical records, customer conversations, and business documents contain valuable facts—but those facts are rarely organized in a format that AI systems can immediately understand. Relation extraction helps bridge this gap. As a key Natural Language Processing (NLP) technique, it […]
Document Classification for Legal and Financial Text
Legal and financial organizations are sitting on vast amounts of information—but much of it remains locked inside unstructured documents. Contracts, court filings, invoices, annual reports, loan agreements, regulatory notices, disclosures, and compliance records all contain valuable information that must be identified, organized, and retrieved quickly. This is where document classification for legal and financial text […]
Text Classification for Intent Detection in Conversational AI
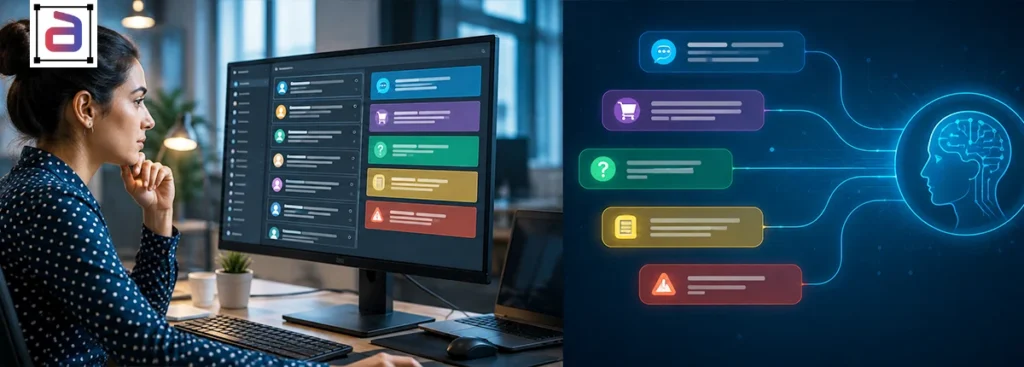
Conversational AI is transforming how businesses interact with customers. From virtual assistants and customer support chatbots to banking bots and voice-enabled applications, modern AI systems are expected to understand what users mean For the multilingual scale of intent classification programs, see the intent classification for global support.. High-quality intent annotation for chatbot success is what […]
Named Entity Recognition (NER): Building Domain-Specific Entity Models
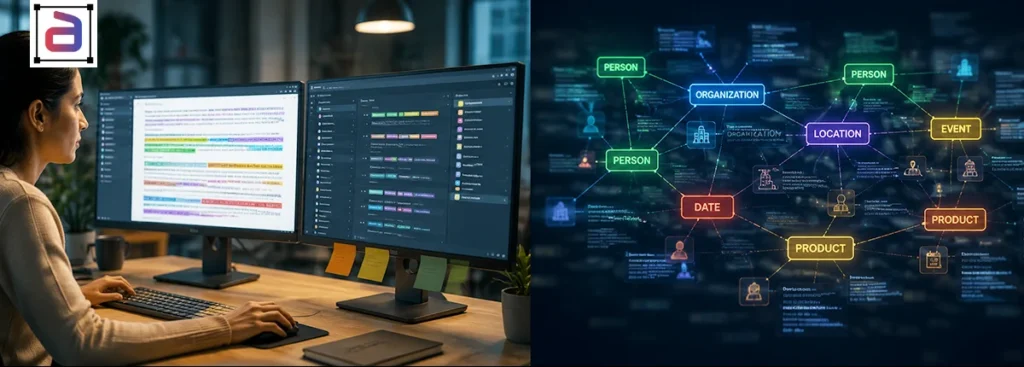
Modern AI systems process enormous volumes of unstructured text—from medical records and financial reports to customer conversations, legal documents, product catalogs, and enterprise knowledge bases. But before AI can understand this information, it must identify the important entities hidden within it. This is where Named Entity Recognition (NER) becomes essential. NER enables NLP systems to […]
Sentiment Analysis Annotation: Capturing Nuance Beyond Positive/Negative/Neutral
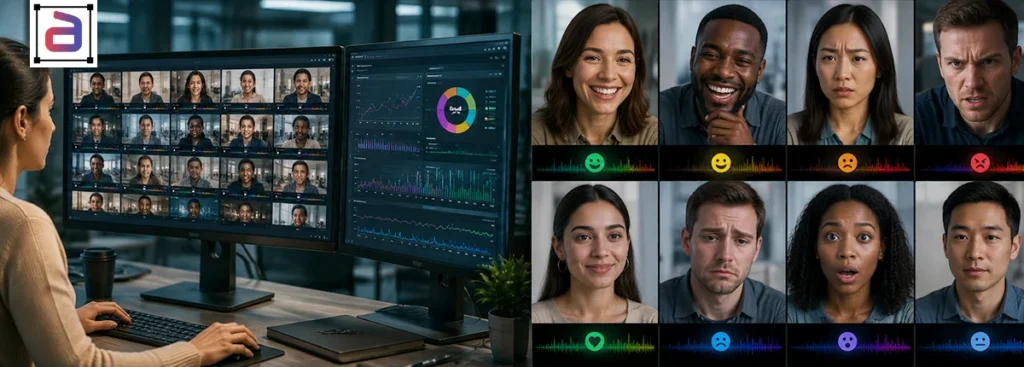
Human language is rarely as simple as positive, negative, or neutral. A customer can praise a product while criticizing its price, express frustration through sarcasm, or feel excited and disappointed within the same sentence. For AI systems to understand these subtle signals, sentiment analysis needs training data that goes beyond basic polarity labels. This is […]
Scalable Text Annotation Workflows for Generative AI Content Moderation
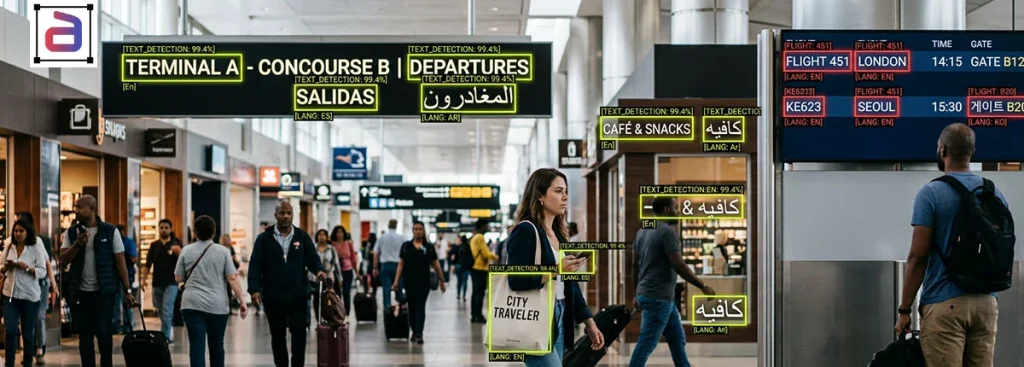
Generative AI is rapidly reshaping the digital economy. From automated customer interactions and AI-generated marketing copy to intelligent virtual assistants and conversational search, businesses are integrating AI into nearly every customer-facing workflow. However, as adoption accelerates, so do the risks associated with unmoderated AI-generated content. Toxic language, misinformation, hallucinations, biased outputs, and harmful content can […]