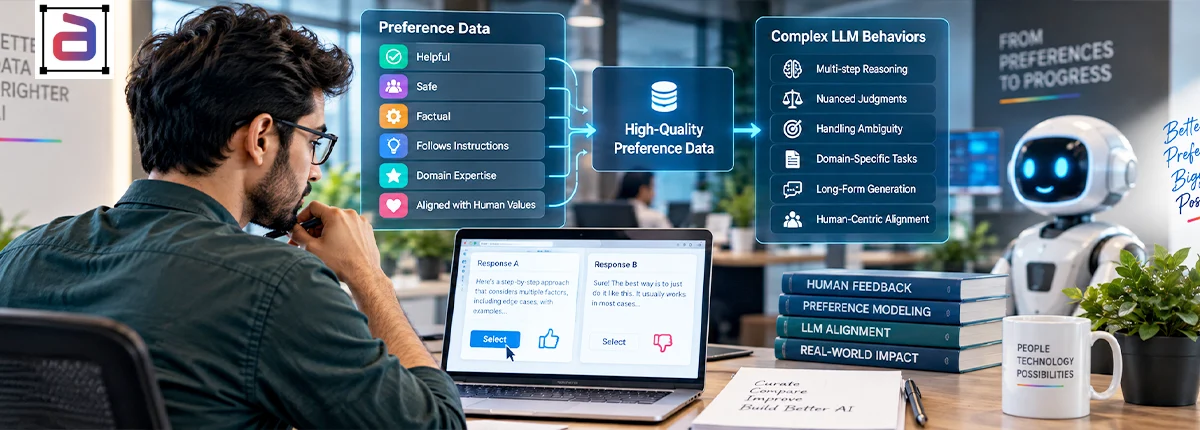
Large language models are becoming increasingly capable, but capability alone does not guarantee that an AI system will behave the way users expect. A model may produce fluent text yet misunderstand an instruction, provide an incomplete answer, overlook important context, or sound confident while presenting questionable information. This is where preference data becomes essential. Human preference signals help model developers distinguish between responses that are merely plausible and those that are genuinely useful, accurate, safe, relevant, and aligned with the intended task.
In the development of InstructGPT, for example, OpenAI collected human demonstrations and rankings of model outputs as part of its reinforcement learning from human feedback (RLHF) process. But as LLM applications become more sophisticated, simply asking annotators to select “Response A” or “Response B” is no longer enough. The future of preference annotation lies beyond response ranking—in building structured, context-aware, high-quality datasets that capture the complex behaviors developers actually want their models to learn.
Key Points
- Go Beyond Simple Ranking: High-quality preference data captures why one LLM response is better by evaluating accuracy, relevance, safety, reasoning, and instruction adherence.
- Context Drives Better Judgments: Preference annotation should consider system instructions, conversation history, reference material, tool outputs, and task-specific requirements.
- Structured Rubrics Improve Data Quality: Clear behavioral criteria, annotator training, calibration, disagreement analysis, and quality assurance create more consistent preference datasets.
- Better Preference Data Enables Better LLMs: Well-designed RLHF & fine-tuning data helps AI teams improve complex model behaviors and build more reliable, context-aware generative AI systems.
Why Simple Response Ranking Has Limitations
Pairwise comparison is powerful because it asks annotators to make a relative judgment rather than assign an absolute score. However, the final preference label can hide valuable information. Imagine two responses to a complex business question. Response A is highly detailed but contains an unsupported assumption. Response B is shorter but factually grounded and directly addresses the user’s objective. If an annotator selects Response B, the preference label tells the training pipeline which response was preferred—but not necessarily why. Was it more accurate? More relevant? Better structured? Less speculative? More aligned with the user’s instructions? For sophisticated LLM training, these distinctions matter. As research on preference data highlights, pairwise preference signals can be relatively sparse and may provide limited information about the reasoning behind a judgment.
From “Which Is Better?” to “Why Is It Better?”
High-quality preference annotation should capture the dimensions that influence the judgment. Depending on the application, these dimensions may include:
- Instruction adherence
- Factual accuracy
- Relevance
- Completeness
- Reasoning quality
- Clarity
- Helpfulness
- Safety
- Tone
- Context awareness
- Appropriate uncertainty
- Policy compliance
This approach creates richer RLHF & fine-tuning data because developers can identify specific behavioral strengths and weaknesses instead of relying exclusively on a single preference label. For example, an annotation workflow could record:
- Preferred response: B
- Primary reason: Better instruction adherence
- Secondary issue with A: Introduces unsupported information
- Safety assessment: No significant concern
- Overall confidence: High
The result is a more informative training signal.
Context Is Part of the Annotation
An LLM response should rarely be evaluated in isolation. The same sentence can be appropriate in one context and problematic in another. A model may have been instructed to respond concisely, use a particular format, rely on a supplied document, or avoid making assumptions. Therefore, preference-data workflows should provide annotators with the relevant context, including:
- System instructions
- User prompts
- Conversation history
- Reference material
- Tool outputs
- Task-specific requirements
- Domain or safety guidelines
Context-aware annotation enables evaluators to judge whether the model actually fulfilled the intended task. For Annotera, this is a critical principle in designing LLM & GenAI annotation services: the objective is not simply to label outputs, but to convert human understanding of the task into consistent, usable training signals.
Build Behavioral Rubrics Before Scaling Annotation
The quality of preference data begins with the annotation rubric. A vague instruction such as “choose the best answer” leaves too much room for subjective interpretation. A stronger rubric defines what “best” means for the specific application. For a customer-service model, helpfulness might mean resolving the customer’s issue efficiently and accurately. Correctness and executable code may carry greater weight than conversational style for a coding assistant. For a research assistant, source grounding and appropriate uncertainty may be critical. For a safety-oriented application, avoiding harmful or unsupported recommendations may take priority over completeness. The rubric should therefore define evaluation criteria, priority rules, edge cases, examples, and escalation procedures before large-scale data collection begins.
Capture Trade-Offs Between Competing Behaviors
Complex LLM behavior often involves trade-offs. A response can be accurate but unnecessarily verbose. Another can be concise but omit essential context. One answer can be highly cautious while another provides more actionable information. Preference annotation needs to make these trade-offs explicit. Annotators should understand questions such as:
- Does factual accuracy take priority over stylistic quality?
- When should the model ask a clarification question instead of making an assumption?
- How much detail is appropriate for the user’s stated objective?
- When does caution become unhelpful refusal?
These decisions transform preference annotation from a simple ranking exercise into a structured behavioral evaluation process.
Annotator Expertise Directly Affects Data Quality
Not every LLM task can be evaluated effectively by a generalist annotator. Specialized applications may require domain knowledge in areas such as finance, healthcare, law, engineering, science, or software development. Consider a technical response that sounds convincing but contains a subtle methodological error. A general evaluator may select it over a less polished but technically correct response. Domain-aware annotation reduces this risk. Annotators should therefore be selected, trained, and calibrated according to the complexity of the task. Clear examples and regular calibration exercises can further improve consistency.
Quality Assurance Should Be Built Into the Pipeline
Scaling preference data without quality controls can amplify inconsistency. A robust workflow can incorporate:
- Annotator training – Establish a common interpretation of the rubric.
- Calibration tasks – Test understanding before production annotation.
- Multiple annotations – Compare judgments across annotators.
- Disagreement analysis – Identify ambiguous or poorly defined cases.
- Expert adjudication – Resolve difficult examples.
- Random audits – Continuously monitor production quality.
- Guideline refinement – Update instructions based on recurring disagreements.
Disagreement itself can be valuable. If multiple trained annotators consistently disagree about a particular type of response, the issue may not be the annotators. It may indicate that the evaluation criteria need to be clarified.
Combine Preference Labels With Structured Rationales
A preference label tells the model which response was preferred. A rationale can explain the behavioral distinction. For example:
“Response B is preferred because it directly answers the user’s question, acknowledges uncertainty around the available evidence, and avoids the unsupported claim present in Response A.”
Such rationales can help with quality control, dataset analysis, and the development of more sophisticated evaluation pipelines. The goal is not to make every annotation unnecessarily lengthy. Instead, rationale requirements should be proportional to task complexity.
Human Feedback Remains Critical for Nuanced Behaviors
Human preferences are particularly valuable when the target behavior is difficult to capture with a simple automated metric. OpenAI’s work on instruction following describes human feedback as useful for alignment problems that are complex and subjective and therefore not fully captured by automatic metrics. This is particularly relevant as LLMs move into real-world applications where “correctness” is only one part of response quality. A model may need to be: Correct + relevant + safe + context-aware + instruction-following + appropriately concise. Preference data provides a mechanism for translating these expectations into training signals.
How Annotera Supports High-Quality Preference Data
At Annotera, we understand that effective LLM training begins with effective data. Our LLM & GenAI annotation services can support workflows involving response evaluation, preference annotation, instruction-following assessment, quality grading, safety evaluation, and domain-specific review. We focus on building annotation workflows around the specific behavior the model needs to learn—not simply producing large volumes of labels. From rubric development and annotator calibration to multi-level quality assurance and structured preference datasets, Annotera helps AI teams create reliable human feedback at scale.
The Next Generation of Preference Data
The evolution of LLMs requires an evolution in how their behavior is evaluated. Response ranking remains an important component of preference learning, but complex AI systems require richer signals. Developers need to understand not only which response wins, but also which behavioral characteristics made it preferable. That means designing datasets around context, behavioral dimensions, trade-offs, expert judgment, consistency, and measurable quality. As preference-based training continues to develop, the organizations that invest in high-quality RLHF & fine-tuning data can create stronger foundations for improving model behavior. Better models begin with better feedback—and better feedback begins with better data.
Build Better Preference Data With Annotera
Whether you are developing an enterprise LLM, conversational AI system, AI agent, or generative AI application, Annotera can help you build structured, scalable, and quality-focused preference datasets. Talk to Annotera today to explore how our LLM & GenAI annotation services can support your preference annotation, RLHF, and fine-tuning data requirements.
A closely related read: LLM Evaluation Datasets: How to Build Human-Graded Benchmarks That Actually Predict Production Quality.