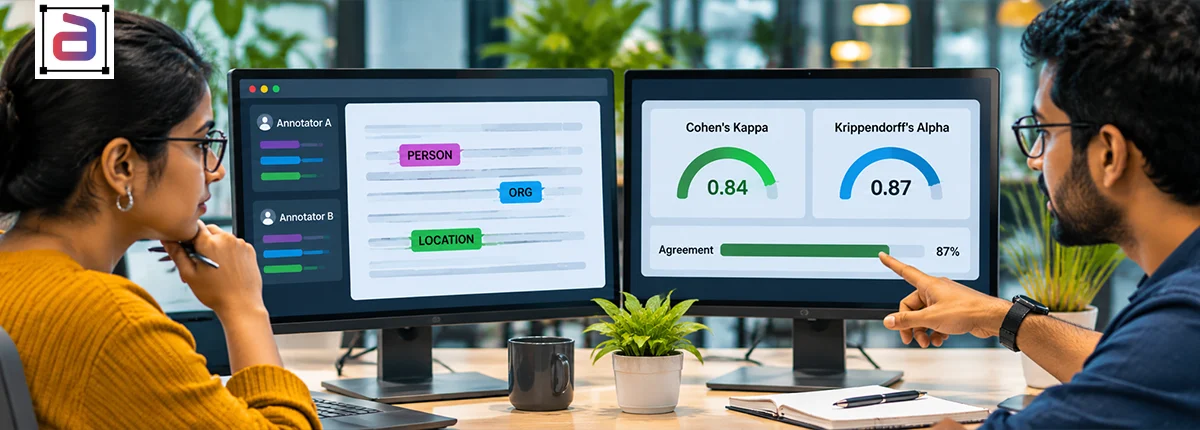
What happens when two annotators read the same customer review but assign completely different sentiment labels? One identifies frustration, while the other interprets the language as neutral feedback. Such inconsistencies may appear minor, but when they occur across thousands of text samples, they can significantly affect the quality of AI training datasets. In Natural Language Processing (NLP), annotation consistency is just as important as annotation accuracy. AI models learn patterns from labeled data, and inconsistent labels can introduce noise, weaken model performance, and create unreliable predictions.
This makes Inter-Annotator Agreement (IAA) a critical quality measurement in professional text annotation workflows. Two statistical methods frequently used to evaluate annotation consistency are Cohen’s Kappa and Krippendorff’s Alpha. Both measure agreement beyond what might occur by chance, helping organizations assess the reliability of their labeled datasets. As an experienced text annotation company, Annotera recognizes that dependable AI systems begin with structured, consistent, and quality-controlled training data. Let’s explore how these agreement metrics work and why they matter for modern NLP applications.
Key Points
- Inter-Annotator Agreement (IAA) measures consistency among annotators and helps ensure reliable, high-quality text annotation datasets for NLP and AI applications.
- Cohen’s Kappa evaluates agreement between two annotators while accounting for chance agreement, making it useful for categorical text labeling tasks.
- Krippendorff’s Alpha supports multiple annotators, missing data, and different measurement scales, making it suitable for complex annotation projects.
- Consistent Annotation Quality Requires Structured Processes: Clear guidelines, annotator training, regular quality audits, and expert adjudication help improve dataset reliability and AI model performance.
What Is Inter-Annotator Agreement in Text Annotation?
Inter-Annotator Agreement measures the degree to which two or more annotators independently assign identical or compatible labels to the same textual data. Consider an intent classification project involving 1,000 customer support queries. Multiple annotators are instructed to classify each query into categories such as refund request, order tracking, product inquiry, or technical support. If annotators consistently assign the same labels to similar queries, the dataset demonstrates strong agreement. However, frequent disagreements may indicate ambiguous guidelines, subjective interpretation, or insufficient training. IAA is particularly valuable for:
- Sentiment Analysis: Ensuring consistent identification of positive, negative, and neutral expressions.
- Named Entity Recognition (NER): Standardizing the identification of people, organizations, locations, and other entities.
- Intent Classification: Ensuring semantically similar customer queries receive consistent intent labels.
- Content Moderation: Maintaining uniform standards when identifying harmful or inappropriate language.
- Text Classification: Improving consistency across document categorization and topic labeling.
However, simply calculating the percentage of matching annotations is not always sufficient. Some agreement may happen by chance. This is why Cohen’s Kappa and Krippendorff’s Alpha are particularly useful.
Understanding Cohen’s Kappa: Measuring Agreement Between Two Annotators
Cohen’s Kappa is a statistical coefficient that measures agreement between two annotators while accounting for the probability of random agreement. Unlike simple percentage agreement, it considers how frequently annotators might select the same labels based on their individual labeling distributions. The formula is: κ = (Pₒ − Pₑ) / (1 − Pₑ) Where:
- Pₒ: Observed agreement between annotators.
- Pₑ: Expected agreement occurring by chance.
- κ: Cohen’s Kappa coefficient.
Practical Example of Cohen’s Kappa
Imagine two annotators independently classify 100 customer reviews into positive, negative, and neutral categories. Their annotations match on 85 reviews, resulting in an observed agreement of 85%. Based on their individual labeling distributions, the expected chance agreement is 50%. Applying the formula: κ = (0.85 − 0.50) / (1 − 0.50) κ = 0.70 A Cohen’s Kappa score of 0.70 indicates substantial agreement under commonly used interpretation guidelines.
How to Interpret Cohen’s Kappa Scores
The following interpretation, proposed by Landis and Koch (1977), is widely referenced:
| Kappa Score | Agreement Level |
|---|---|
| Below 0.00 | Poor |
| 0.00–0.20 | Slight |
| 0.21–0.40 | Fair |
| 0.41–0.60 | Moderate |
| 0.61–0.80 | Substantial |
| 0.81–1.00 | Almost perfect |
These ranges are interpretive guidelines rather than universal quality benchmarks. Acceptable thresholds should reflect the complexity and risk of the annotation task. Why does this matter? In a high-volume text annotation project, a strong agreement score provides evidence that annotators are applying labeling instructions consistently. However, it should always be evaluated alongside expert reviews and task-specific quality checks.
Understanding Krippendorff’s Alpha: A Flexible Approach to Annotation Reliability
While Cohen’s Kappa is designed for two annotators, Krippendorff’s Alpha offers greater flexibility for complex annotation environments involving multiple annotators. Developed by Klaus Krippendorff, this statistical measure evaluates agreement by comparing observed disagreement with the disagreement expected by chance. Its general formula is: α = 1 − (Dₒ / Dₑ) Where:
- Dₒ: Observed disagreement.
- Dₑ: Expected disagreement.
- α: Krippendorff’s Alpha coefficient.
A score of 1 represents perfect agreement, while 0 indicates agreement no better than expected by chance. Negative scores indicate greater disagreement than expected under the chance model.
What Makes Krippendorff’s Alpha Different?
Krippendorff’s Alpha is particularly useful for large-scale NLP projects where annotation assignments and labeling requirements may vary. Its major advantages include: 1. Multiple Annotators It supports two or more annotators, making it suitable for large-scale annotation teams. 2. Missing Data Handling It can accommodate incomplete annotations, allowing projects to evaluate reliability even when not every annotator labels every sample. 3. Different Measurement Scales It supports nominal, ordinal, interval, and ratio-level measurements through appropriate disagreement functions. 4. Flexible Annotation Applications It can be applied to sentiment analysis, document classification, content categorization, and other NLP tasks. For example, consider a dataset of customer support conversations reviewed by five annotators. Krippendorff’s Alpha can evaluate overall agreement even if certain conversations have been reviewed by only three or four annotators.
Cohen’s Kappa vs. Krippendorff’s Alpha: Which Should You Choose?
Both metrics help evaluate annotation consistency, but their suitability depends on the project’s structure.
| Comparison Factor | Cohen’s Kappa | Krippendorff’s Alpha |
|---|---|---|
| Number of Annotators | Two | Two or more |
| Missing Data | Requires complete paired observations | Accommodates missing observations |
| Measurement Scales | Primarily nominal categories | Nominal, ordinal, interval, ratio |
| Complexity | Relatively straightforward | More flexible |
| Ideal Application | Two-annotator labeling tasks | Multi-annotator projects |
Which metric is better? There is no universal winner. Cohen’s Kappa is a practical choice for projects involving two annotators and categorical labels. Krippendorff’s Alpha is generally more suitable when multiple annotators, incomplete observations, or different measurement scales are involved. The objective is not simply to achieve a higher statistical score. It is to understand annotation disagreements and improve the underlying labeling process.
5 Best Practices to Improve Inter-Annotator Agreement
Measuring agreement is only the beginning. Organizations must establish repeatable quality management processes to maintain annotation consistency. 1. Develop Comprehensive Annotation Guidelines Define every label clearly, provide contextual examples, and explain how to handle ambiguous expressions. Clear instructions reduce subjective interpretation. 2. Conduct Pilot Annotation Exercises Before beginning large-scale labeling, ask multiple annotators to independently label a small dataset. Compare their results and identify areas requiring clarification. 3. Implement Regular Quality Audits Review annotated samples periodically and monitor agreement scores. Investigate recurring disagreements rather than simply correcting individual labels. 4. Provide Continuous Annotator Training Calibration exercises and feedback sessions help annotators understand complex linguistic contexts and apply updated labeling standards consistently. 5. Establish an Adjudication Process When disagreements occur, experienced reviewers should evaluate the context, determine the appropriate label, and document the decision for future reference. As the American statistician W. Edwards Deming famously emphasized: “Quality is everyone’s responsibility.” This principle applies directly to annotation operations. Reliable datasets emerge when quality management is integrated into every stage of the labeling workflow.
How Annotera Strengthens Text Annotation Quality and Consistency
At Annotera, we believe that high-quality AI training data requires more than annotation volume. It demands consistency, contextual understanding, structured workflows, and measurable quality assurance. Our text annotation outsourcing services help organizations develop reliable datasets for NLP applications, conversational AI, sentiment analysis, intent classification, and large language models. Our approach focuses on:
- Standardized Annotation Guidelines: Establishing clear labeling frameworks aligned with project objectives.
- Trained Annotation Teams: Supporting consistent interpretation across complex text labeling assignments.
- Multi-Level Quality Assurance: Incorporating review mechanisms to identify and resolve annotation inconsistencies.
- Disagreement Management: Evaluating conflicting labels through structured review and adjudication.
- Scalable Annotation Operations: Supporting large-volume text annotation requirements without compromising established quality standards.
Whether your organization is developing an intelligent chatbot, training an LLM, or building advanced sentiment analysis capabilities, Annotera helps establish the data quality foundations required for dependable AI performance.
Conclusion: Build More Reliable NLP Models Through Consistent Annotation
Inter-Annotator Agreement is an essential measure of reliability in text annotation. Cohen’s Kappa helps quantify agreement between two annotators, while Krippendorff’s Alpha provides greater flexibility for multi-annotator projects and datasets containing missing observations. However, statistical agreement alone cannot guarantee annotation quality. Clear guidelines, trained annotators, continuous quality audits, and expert adjudication must work together to produce dependable datasets. For organizations developing next-generation NLP and generative AI solutions, investing in consistent annotation practices is a strategic necessity. Looking for reliable text annotation outsourcing services for your next AI project? Partner with Annotera. Our expert-driven annotation workflows, structured quality assurance processes, and scalable delivery capabilities help transform complex textual information into high-quality AI training datasets. Connect with Annotera today and build the foundation for more accurate, consistent, and reliable AI models!